liveBook · Manning

JSON Schema Faker

As explained in Data-Oriented Programming: Reduce software complexity

JSON Schema Faker is a library that generates randomized data conforming to JSON Schema definitions.

JSON Schema Faker generates randomized data that conforms to a JSON Schema, turning schemas into practical inputs for automated tests. section 12.5

A schema-based test uses it to:

  • Generate random arguments matching a function’s input schema. section 12.5
  • Exercise simple schemas such as UUIDs and larger schemas such as catalogs. section 12.5
  • Expose invalid return data through schema validation and failure output. section 12.5

Testing a catalog search

Generate a catalog and query, call Catalog.searchBooksByTitle, and validate the returned value. A failing run exposes malformed authorNames data; fixing the lookup makes the test pass. section 12.5
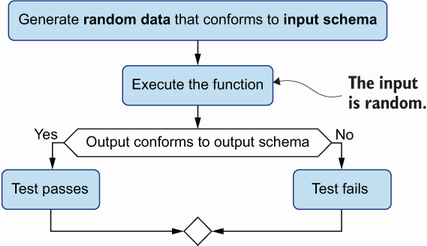
Figure 12.3 The flow of a schema-based unit test

The flow diagram connects generated inputs, function execution, and schema validation of the result. section 12.5

How Data-Oriented Programming: Reduce software complexity covers it

How deep it goes
Demonstrates UUIDs, nested catalogs, test integration, and debugging through return-schema failures.
Examples
Uses UUIDs, randomized catalogs, and Catalog.searchBooksByTitle tests.
What it assumes
Assumes JSON Schema definitions and function-level unit tests, while demonstrating the generation workflow.
What you can do after
Diagnose/debug with it by generating varied valid inputs and tracing failures against declared schemas.
How it connects
Connects JSON Schema with unit testing, data validation, and return-value validation.

Related concepts

This explainer was generated by Manning's knowledge graph from the text of Data-Oriented Programming: Reduce software complexity. The section links point to the parts of the book it draws on.