A known-known is a condition that can go wrong and whose specific behavior is already understood. Observability can therefore define the healthy boundary, query for violations, alert reliably, and sometimes restore the system automatically. section 5.1.3
Treat known-knowns as explicit operational contracts:
- Measure the signals that identify the known healthy state. section 5.1.3
- Query and alert when a defined boundary is violated. section 5.1.3
- Develop self-healing strategies when the failure and remedy are predictable. section 5.1.3
Platform operations
A Kubernetes cluster sustaining CPU activity above 90% signals that scaling is not working as expected. Load testing may establish that a source-control project API handles only ten simultaneous requests. Telemetry and alerts can expose both limits before they disrupt users. section 5.1.3
Figure 5.3 Knowing what to look for when querying observability data is an evolving process.
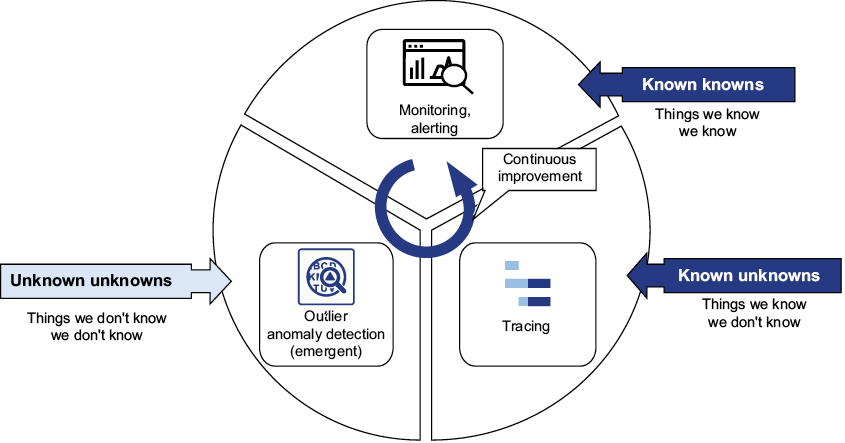
Use the figure to distinguish what observability teams can query for now from conditions they must learn to recognize over time. section 5.1.3
