KServe is a Kubernetes-based model serving platform for deploying machine learning models across arbitrary frameworks. It addresses production serving concerns through a standardized custom resource and high-abstraction interfaces. section 8.3
KServe packages operational behavior that model deployments commonly need:
- Autoscale serving workloads, including GPU-backed deployments and scale-to-zero behavior. section 8.3 section 9.5
- Handle networking, health checking, and model-server configuration through Kubernetes-native resources. section 8.3
- Support canary rollouts and replicated model servers for production deployment workflows. section 8.3 section 9.5
End-to-end serving workflow
A distributed TensorFlow pipeline can train a model in a Kubernetes cluster, then deploy either a single-instance or replicated model server through KServe. As request volume increases, KServe creates additional serving Pods. section 9.5
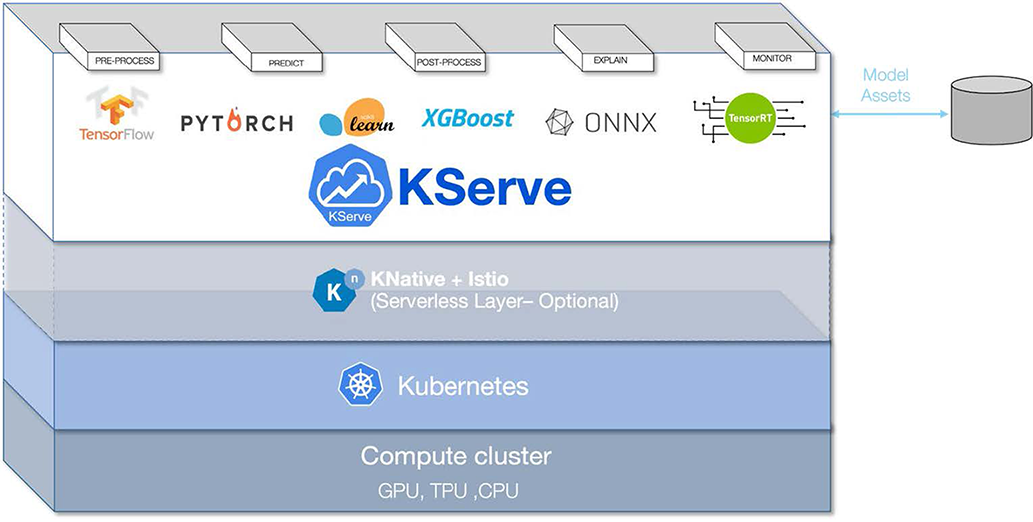
Use the ecosystem diagram to locate KServe among Kubeflow components and understand its role in the machine-learning lifecycle. section 8.3

