Use the unmodified Llama-3.2-3B as a vLLM reference before testing a pruned version. With float16, eager execution, and a 2,048-token maximum length, a Colab T4 run reserved 5.63 GiB for the KV cache (52,720 tokens) and generated at 33.55 ms per token. Treat the timing as a comparison point, not a definitive benchmark. section 12.6.2
Pruning trades memory for quality. Removing 3 or 6 layers reduced dynamic VRAM by 12.3% or 28.2%, with limited changes on four benchmarks but larger Lambada drops. Removing 15 layers cut dynamic VRAM by 46.5%, while benchmark scores collapsed. section 8.4.2
Figure 8.10 Benchmark scores for Llama-3.2-3B across four configurations. Degradation between 3 and 6 layers removed is negligible across all benchmarks, but Lambada shows progressive sensitivity to attention pruning at all ratios, and collapses almost completely at 15 layers removed, along with the rest of the tasks.
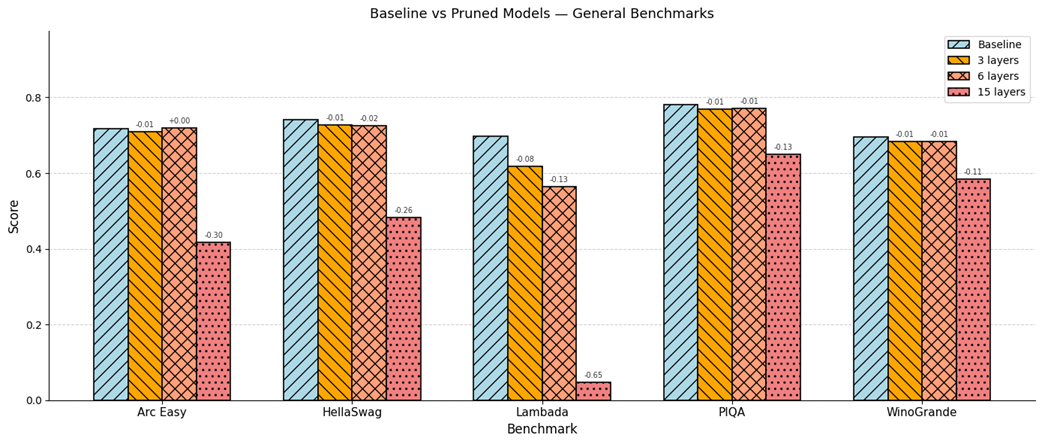
Compare benchmark degradation across the original model and three pruning configurations. section 8.4.2
Table 8.2 Dynamic VRAM delta across pruning configurations
|
Configuration
|
Dynamic VRAM
|
Vs Baseline
|
|
Baseline
|
109.57 MB
|
_
|
|
3 layers removed
|
96.06 MB
|
-12.3%
|
|
6 layers removed
|
78.72 MB
|
-28.2%
|
|
15 layers removed
|
58.63 MB
|
-46.5%
|
Review dynamic VRAM measurements for the baseline and each pruning configuration. section 8.4.2
