LLVM IR is the stage where Triton hands most remaining compilation work to LLVM. Tensor-level abstractions have become per-thread operations: memory instructions are explicit, synchronization is concrete, and arithmetic maps to device intrinsics. section 2.3.1
In Triton’s compilation path:
- GPU-aware TTGIR lowers to LLVM IR, where optimization proceeds per instruction. section 2.3.1
- LLVM IR translates to NVIDIA PTX, which is assembled into a CUBIN binary executed by the GPU. section 2.3.1
Inspecting a compiled kernel
After launching a Triton kernel, retrieve its LLVM IR from the compiled object with compiled.asm["llir"]. Saving this representation can help investigate unexpected behavior or performance. section 2.3.2
Figure 2.10 The Triton compiler pipeline: from user code through AST, TTIR, and TTGIR to GPU execution via LLVM-IR, PTX, and CUBIN.
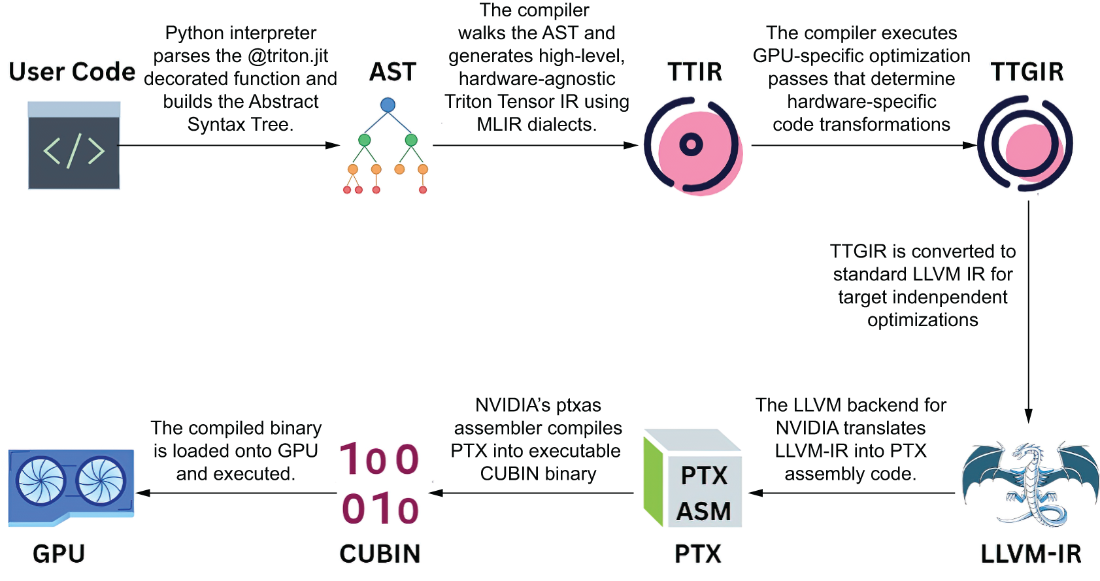
Follow the compiler pipeline from user code through Triton’s intermediate representations to LLVM IR, PTX, and CUBIN. section 2.3.1
