loadSummarizationChain is a LangChain.js factory that builds a document-summarization chain from an LLM and configuration options. It supports multiple workflows for turning loaded, optionally chunked documents into a final summary. section 7.1.3
Choose the strategy according to document size, context limits, and operational trade-offs:
- MapReduce summarizes chunks independently, organizes the intermediate summaries, and reduces them into one combined result. It suits documents that exceed the model context window. section 7.1.2
- Stuff sends the entire document in one prompt and works best when the document fits inside the context window; longer or complex documents can strain this approach. section 7.1.2
- Refine creates an initial summary, then iteratively updates it with each subsequent chunk. It preserves prior output but can propagate early summary errors. section 7.1.2
- Chunk documents before summarization when necessary; overlap preserves context across chunk boundaries and enables strategies such as MapReduce. section 7.1.3
Run a MapReduce summary
import { loadSummarizationChain } from "langchain/chains"; const chain = loadSummarizationChain(model, { type: "map_reduce", verbose: true, }); const result = await chain.invoke({ input_documents: documentChunks, }); console.log("Summarization Result:", result); The factory receives the model first and an options object second. Invoke the returned chain with input_documents containing the loaded or split documents. Large-document requests may take several seconds and consume provider credits; model and provider selection affect cost and reliability. section 7.1.3
Figure 7.1 The architecture of a document summarization system integrating LangChain.js and the Vercel AI SDK. The user uploads a document, which is processed by LangChain.js; it checks if the document exceeds the context window, splits it into chunks, and summarizes each chunk using LLMs. The individual summaries are then combined by the summarization (LLM) component, which is displayed to the user through the UI.
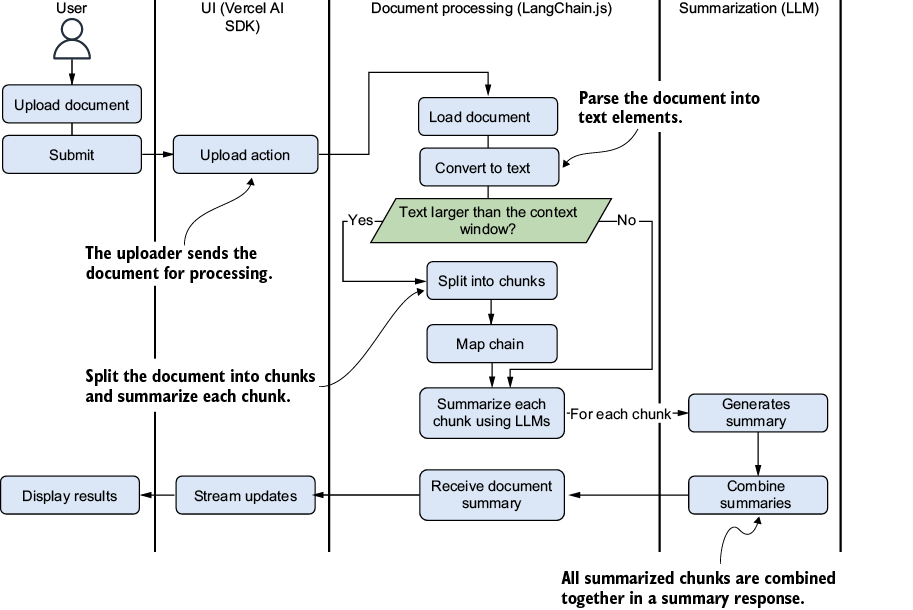
Trace the production flow from document upload through context-window checking, chunking, LLM summarization, combination, and UI display. section 7.1.2
Figure 7.2 The MapReduce summarization pattern, behind the scenes. The input document is divided into smaller chunks. Each chunk is then processed independently by the map function, generating intermediate summary pairs. These pairs are subsequently organized and are grouped together. The reduce step is then applied to these grouped pairs, aggregating the values to produce a final summary.
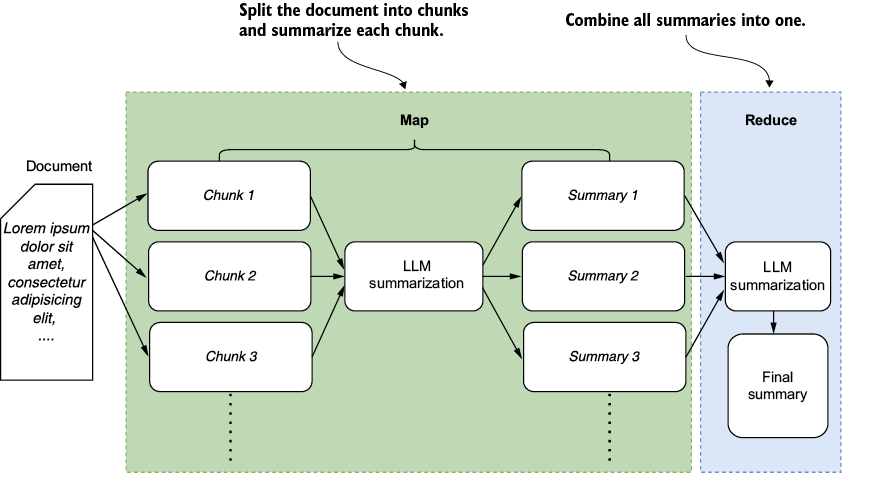
Inspect how MapReduce processes document chunks independently, groups intermediate summaries, and aggregates them into a final result. section 7.1.2
