A log-mel STFT converts short-time spectral magnitudes into logarithmic mel-frequency features. In edge audio pipelines, generating them can take as long as—or longer than—the model inference that follows: the measured cost is about 22 ms on M3 with Accelerate.vDSP and 243 ms on Pixel with a Kotlin radix-2 STFT. section 11.5
Figure 11.12 Pre/post breakdown by modality and device, log y-axis. M3 vision (Python PIL or OpenCV) reads ~30 ms decode + ~17 ms resize + ~3 ms normalize, totalling ~50 ms, already above the 33 ms frame budget for a 30 fps camera before inference begins. M3 audio reads ~11 ms decode + ~22 ms log-mel via Apple Accelerate.vDSP, totalling ~33 ms. M3 text reads ~0.8 ms tokenize + ~0.1 ms detokenize via Hugging Face Rust-backed tokenizers for a 128-token Llama prompt. Pixel vision reads ~0.4 ms decode + ~0.1 ms resize + ~4.7 ms normalize via BitmapFactory + Canvas + Kotlin normalize loop, totalling ~5.3 ms, faster than every M3 vision pipeline measured. Pixel audio reads ~243 ms log-mel via a Kotlin radix-2 STFT implementation, two orders of magnitude slower than M3 Accelerate.vDSP on the same Whisper-tiny feature pipeline.
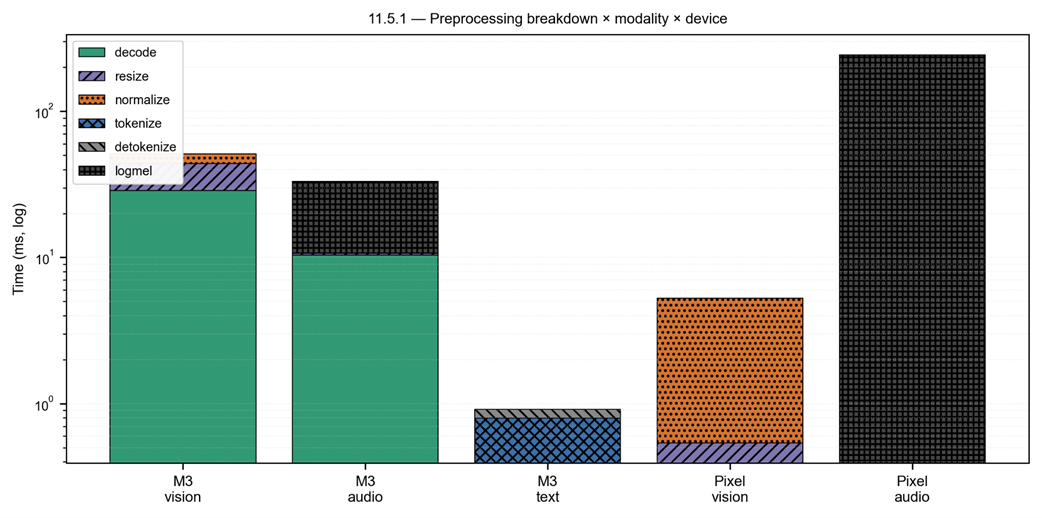
Compare audio preprocessing and inference costs across M3 and Pixel; the portable Pixel implementation makes feature generation a major latency bottleneck. section 11.5
For user-facing audio workloads:
- Measure end-to-end p95 latency, not just the model's forward pass. section 11.6
- Use native platform primitives where available; otherwise, consider putting STFT-class operations in the graph or binding a tuned FFT through JNI. section 11.6
