A low-rank matrix represents a compact parameter update whose rank is much smaller than the dimensions of the original weight matrix. In LoRA, these matrices adapt a pretrained language model without replacing its full architecture or changing its original weights. section 9.6.1
LoRA uses low-rank matrices to make model adaptation more efficient:
- Inserts small matrices into attention and feed-forward layers while the pretrained weight matrix remains frozen. section 9.6.1
- Trains only the adaptation parameters, reducing the computation and storage needed for task-specific fine-tuning. section 9.6.1
- Preserves most pretrained knowledge while enabling specialization, helping reduce the risk of catastrophic forgetting. section 9.6
- Stores and loads a small set of task-specific parameters alongside the pretrained model for downstream adaptations. section 9.6.1
LoRA reparameterization
A layer receives input X and uses its original pretrained weight W together with adaptation matrices A and B. Fine-tuning updates A and B, while W stays frozen. section 9.6.1
Figure 9.14 LoRA reparameterization—only A and B are trained [9]
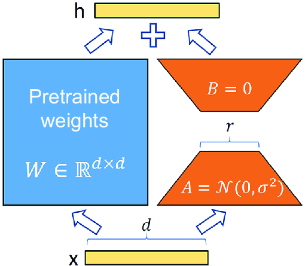
Inspect the reparameterization diagram showing that LoRA trains only A and B while preserving W. section 9.6.1
