A low-rank subspace captures changes using fewer independent directions than the full space permits. In fine-tuning, weight updates may have this structure, so LoRA represents them with two smaller matrices rather than changing the original weights. section 11.3
A compact adapter
For a 4096 × 4096 weight matrix, a rank-16 LoRA adapter adds 131,072 parameters, less than 1% of the original matrix’s 16.8 million. section 11.3
Figure 11.3 LoRA architecture for a single linear layer.
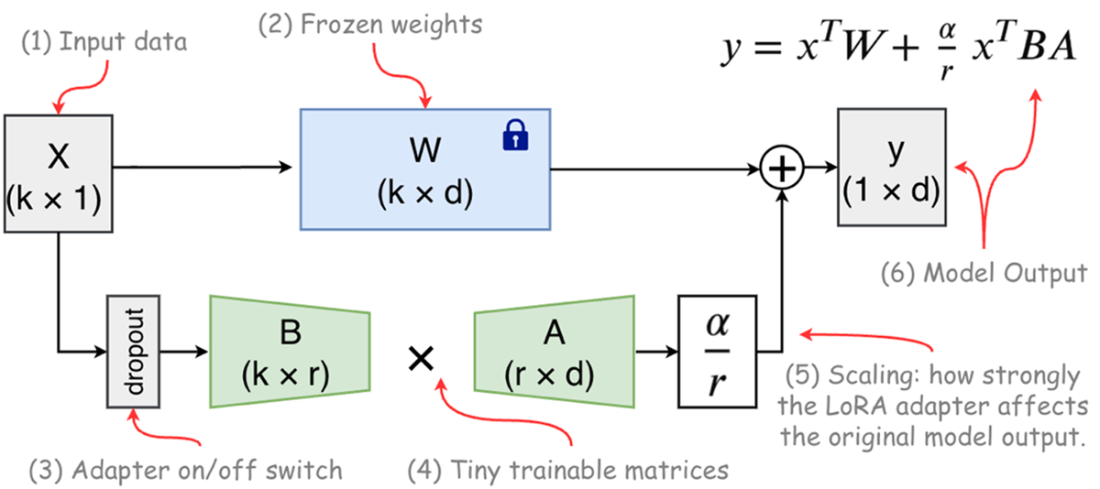
Use the single-layer diagram to see how LoRA adds a low-rank adapter path alongside frozen weights. section 11.3
