A manifest list is snapshot-level Apache Iceberg metadata: each snapshot points to one manifest list, which references manifest files and stores summary statistics. Query engines use it to exclude irrelevant data before scanning files. section 2.3 section 10.1.3
The metadata hierarchy separates responsibilities:
- metadata.json records snapshots, schemas, partition specifications, and table history. section 2.3
- The manifest list represents the active snapshot and references its manifest files. section 10.1.3
- Manifest files track individual Parquet files, paths, partition summaries, and column statistics. section 2.3
Pruning a January query
For a query requiring only January 2024 data, manifest-list statistics can exclude unnecessary partitions; manifest files can then exclude individual Parquet files before any data scan. section 2.3
Figure 2.4 Engines use metadata statistics to exclude data files from scans, speeding up queries.
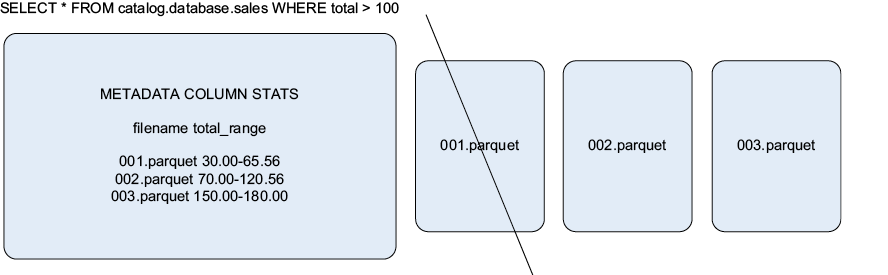
Shows how metadata statistics exclude data files from scans and reduce query cost. section 2.3
Figure 10.4 Metadata bloat occurs when you have more manifests than necessary for the number of data files, or you have manifests tracking too many small data files. Both will delay query planning.
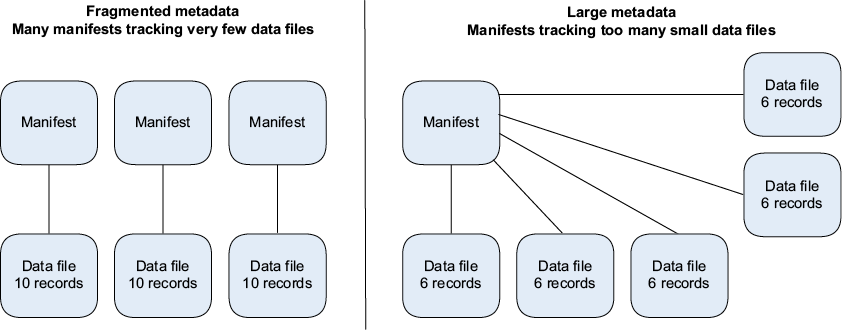
Illustrates how excessive or fragmented manifests delay query planning. section 10.1.3

