Intermediate size is the width of an MLP’s internal expansion. Reducing it through width pruning can cut parameters, compute, and model memory while preserving the hidden size passed between transformer blocks. Actual inference gains depend on the hardware bottleneck and the resulting dimensions. section 5.1 section 5.2.6
Figure 5.1 The complete GLU structure. Information enters with dimension hidden_size (2048 in Llama-3.2-1B) and expands to intermediate_size (8192) via gate_proj and up_proj. The gate_proj output, modulated by SiLU, is element-wise multiplied with up_proj’s output. The result is contracted back to hidden_size by down_proj.
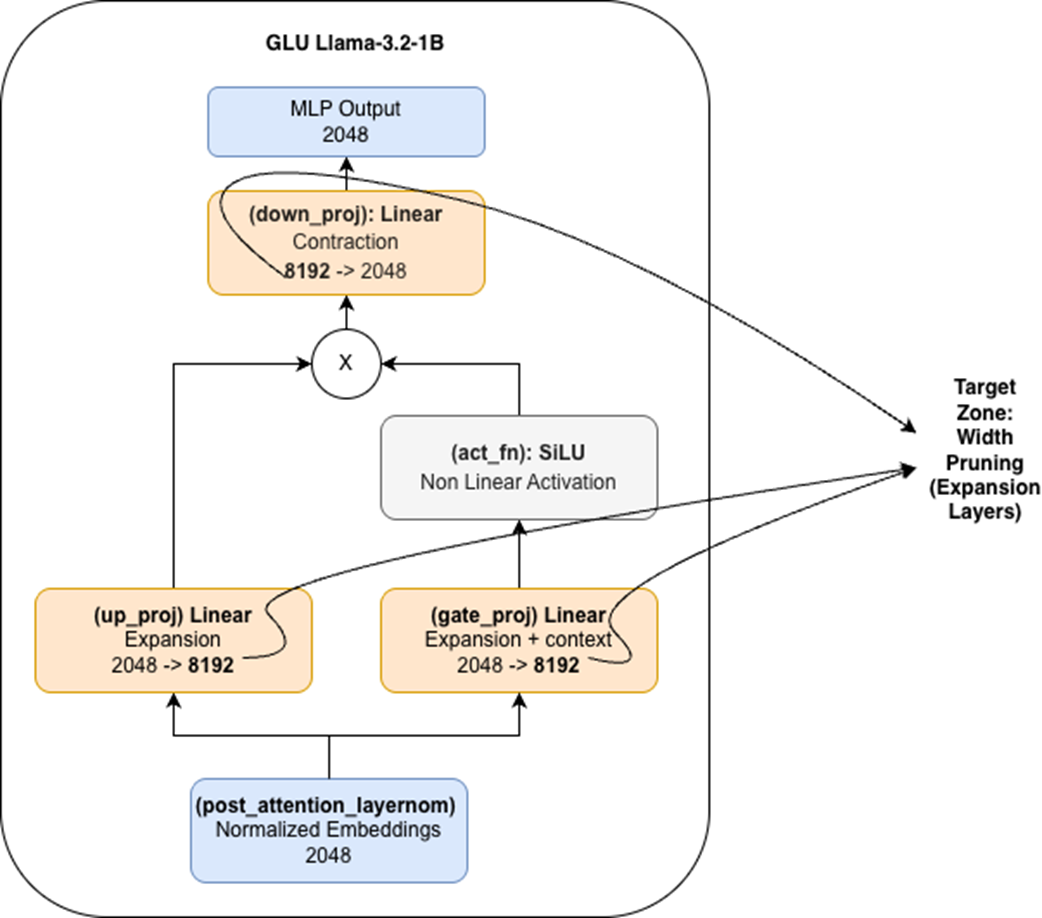
The GLU expands hidden_size through gate_proj and up_proj, combines their outputs, and contracts the result through down_proj. section 5.1
For Llama-3.2-1B, the input hidden size is 2048 and the intermediate size is 8192. The gate and up projections each produce 8192 values; SiLU modulates the gate output before element-wise multiplication with the up output. The down projection returns the result to 2048 dimensions. section 5.1
To narrow a GLU MLP while preserving its connections:
- Score corresponding gate and up neurons together. A peak-to-peak magnitude method combines their weight ranges and selects low-scoring pairs for removal. section 5.1
- Choose the retained width k, cap removal so at least one neuron remains, and use torch.topk to select the highest-scoring pairs. Sort the retained indices back into their original order. section 5.1.2
- Build smaller projections, copying matching gate and up rows and down-projection columns. Replace the projections in each block and update model.config.intermediate_size to the new width. section 5.1.2
Listing 5.2 Orchestrating pruning across all blocks
def update_model(model, prune_percent):

    new_intermediate_size = None
    for idx, layer in enumerate(model.model.layers): #A

        mlp = layer.mlp #1

        new_gate_proj, new_up_proj, new_down_proj, new_size = prune_neuron_pairs(mlp, prune_percent) #2

        mlp.gate_proj = new_gate_proj #3
        mlp.up_proj = new_up_proj #3
        mlp.down_proj = new_down_proj #3
        new_intermediate_size = new_size

    model.config.intermediate_size = new_intermediate_size #4

    return model
This orchestration updates every block’s MLP and records the resulting intermediate size in the model configuration. section 5.1.2
Check the exact rounding policy when calculating a pruning target. For 40% of 8192 neurons, the shown code truncates 3276.8 to 3276, retaining 4916; rounding the removal to 3277 instead retains 4915. The implementation converts weights to float32 for scoring, which can reduce rounding issues but increase memory use. section 5.1.2
For GPU deployment, consider aligning the retained width to a multiple such as 64 or 128. Unaligned dimensions can require padding, while different widths across blocks may not match a serving engine’s model definition. Alignment matters most in compute-bound workloads; benchmark on the target hardware rather than assuming a speedup. section 5.2.6 section 12.5
