Masked language modeling (MLM) pretrains encoder models by hiding a token and predicting it from both left and right sequence context. This bidirectional objective helps produce contextual embeddings for downstream NLP tasks. section 2.3.1
Toy prediction
Given “The chef cooked [MASK] the meal,” the model predicts the missing token from the surrounding sentence, such as “the.” section 2.3.1
Figure 2.5 The two images depict the difference between language modeling and masked language modeling which gives BERT an advantage over traditional left-to-right sequences.
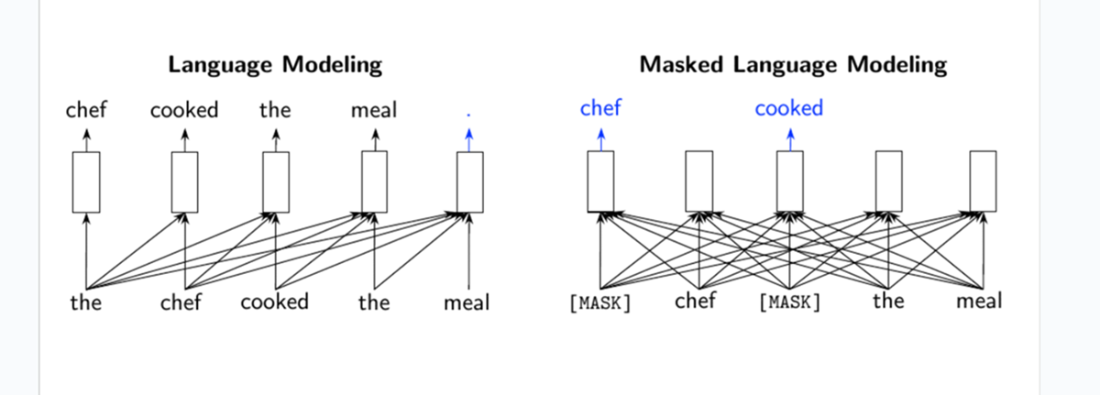
Compare ordinary left-to-right language modeling with bidirectional masked prediction. section 2.3.1





