A memory limitation occurs when training data or a neural network exceeds the capacity of a local compute device, terminating training with an out-of-memory error. Data parallelism improves training speed but does not remove this constraint. section 4.2.1
Address the limitation according to what exceeds device memory:
- Reduce the batch size when loading training data causes OOM; ensure each minibatch fits into every worker’s memory. section 4.2.1
- Adopt model parallelism or pipeline parallelism when the neural network itself exceeds one device’s capacity. section 4.2.1
Figure 4.1 A synchronous data parallelism concept graph. (a) Deep learning training on a single GPU. (b) Synchronous data parallel training with three GPUs.
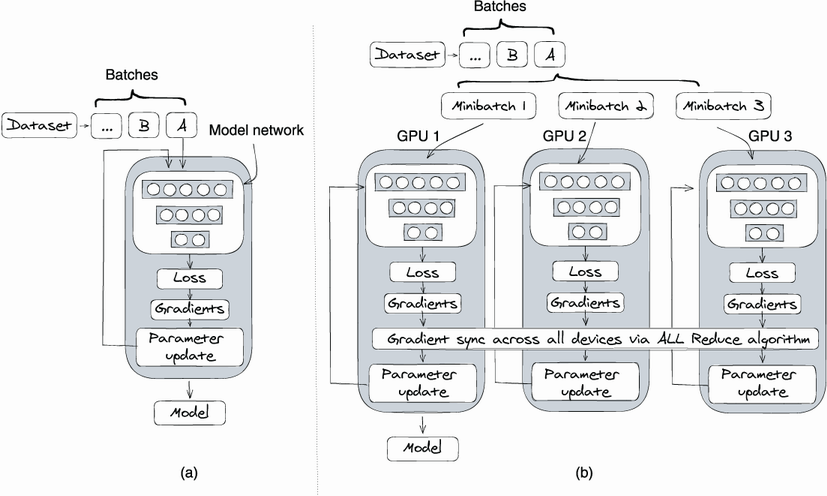
Compare single-device training with synchronous data parallelism and see why adding workers does not by itself solve per-device memory limits. section 4.2.1
