Mixed precision combines lower-precision and higher-precision numeric formats during training or inference. It reduces memory use and can improve speed without the performance degradation of pure FP16. section 6.1
Operationally, mixed precision uses different formats for different parts of the workload:
- During training, weights and computations can use FP16, gradients can be converted back to FP32 for numerical stability, and scaled gradients update the original weights. section 6.1
- During inference, FP16 plus FP32 uses more memory than pure FP16 but less than pure FP32, with comparable and sometimes better performance. section 6.1
- Lower precision helps models fit hardware constraints: FP16 uses about half the FP32 memory, while INT8 reduces it further. section 4.2
Inference sizing
A 2.7-billion-parameter GPT-Neo model requires about 12.96 GB in FP32 and 5.4 GB in FP16. Mistral 7B requires about 33.6 GB in FP32 or 16.2 GB in FP16. section 4.2
Figure 6.2 Representation of 16-bit floating point numbers
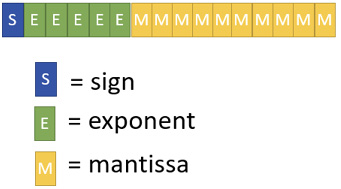
Use the FP16 representation diagram to compare its sign, exponent, and mantissa allocation with FP32. section 6.1


