A mixture of experts (MoE) divides a model into separate expert networks that specialize in handling different tokens or contexts. A gating network, also called a router, decides how much each expert contributes to the output. section 2.6
A sparse MoE activates only a few experts for each input, leaving many parameters inactive. This contrasts with a traditional transformer, which activates all parameters, and with a dense MoE, which combines every expert’s prediction. Selective activation aims to support larger or more specialized models without proportional computational costs, while addressing tradeoffs involving latency, speed, and expense. section 2.0 section 2.6
Routing work to specialists
The architecture resembles an organization that routes each task to employees with the strongest relevant skills. Model experts might specialize in punctuation or parts of speech, rather than in broad human subjects such as science or mathematics. section 2.6
Figure 2.6 A visualization of the Mixture of Experts layer of a neural network
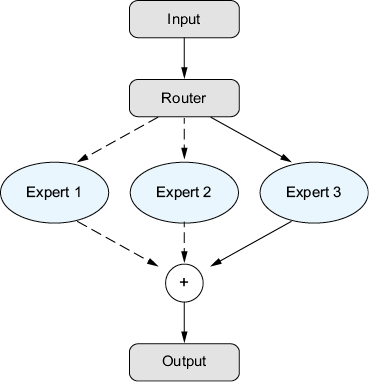
A three-expert layer visualization makes sparsity concrete: only one shown expert contributes to the output. section 2.6



