A model repository is a filesystem-based collection of directories and files that stores deployable model artifacts. Serving systems discover artifacts there, load selected versions, and expose them through inference APIs. section 7.4.3 section 7.4.1
A repository connects storage to the serving lifecycle:
- Triton loads models from repository directories, creates a configurable scheduler for each model, and dispatches requests to the matching backend. section 7.4.3
- TensorFlow Serving locates a servable in the filesystem, associates it with a version and loader, and applies a predefined version policy before loading it. section 7.4.1
- Repository contents must match the serving system’s expected artifact format, such as TensorFlow SavedModel directories containing assets, variables, and saved_model.pb. section 7.4.1
Versioned TensorFlow Serving layout
A model directory can contain versioned subdirectories such as tf_model/1. TensorFlow Serving can mount that directory, select configured versions, and answer requests using a version-specific REST endpoint. section 7.4.1
Figure 7.10 Triton Inference Server high-level architecture (Source: NVIDIA Developer, https://developer.nvidia.com/nvidia-triton-inference-server)
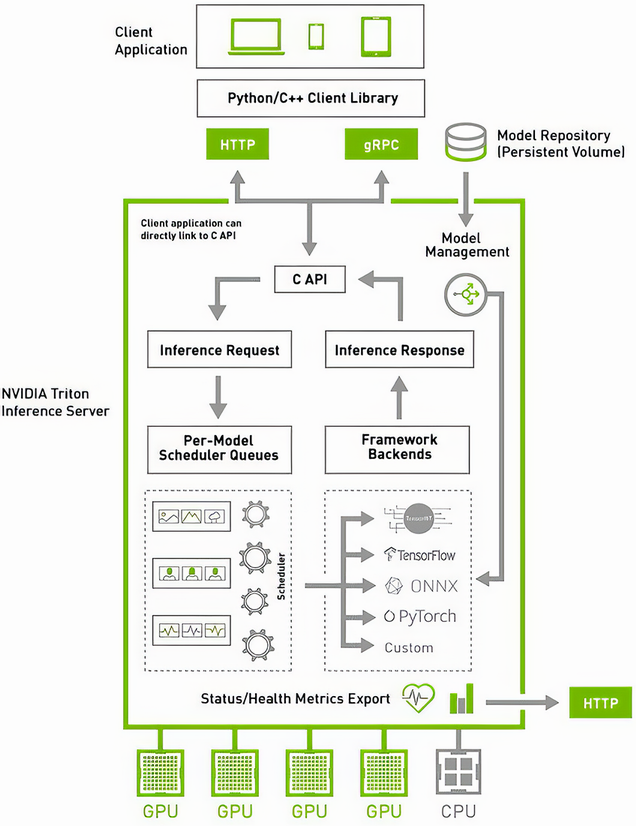
Use the Triton architecture to trace requests from REST or gRPC entry points through repository-loaded models, schedulers, and backends. section 7.4.3

