Place a separate moderation layer between generation and delivery. Treat the model as untrusted and screen every output before it reaches users; at minimum, deploy one classifier. Layered controls can catch both explicit violations and subtler, domain-specific harms. section 6.5.1
Operationalize the layer with complementary controls:
- Use classifiers such as Llama Guard or ShieldGemma, or managed services such as AWS Guardrails for Bedrock and Azure AI Content Safety. section 6.5.1
- Define forbidden topics and conversation flows with NeMo Guardrails; its conversation-state tracking can help catch harms that emerge across turns. section 6.5.1
- Complement classifiers with regex or keyword rules, and validate LLM-as-judge tools against real examples and adversarial pressure. Include soft violations such as blame, fraud speculation, or dismissive tone. section 6.5.1
Figure 6.10 A seven-step workflow for implementing operational assurance for ethical and trustworthy AI.
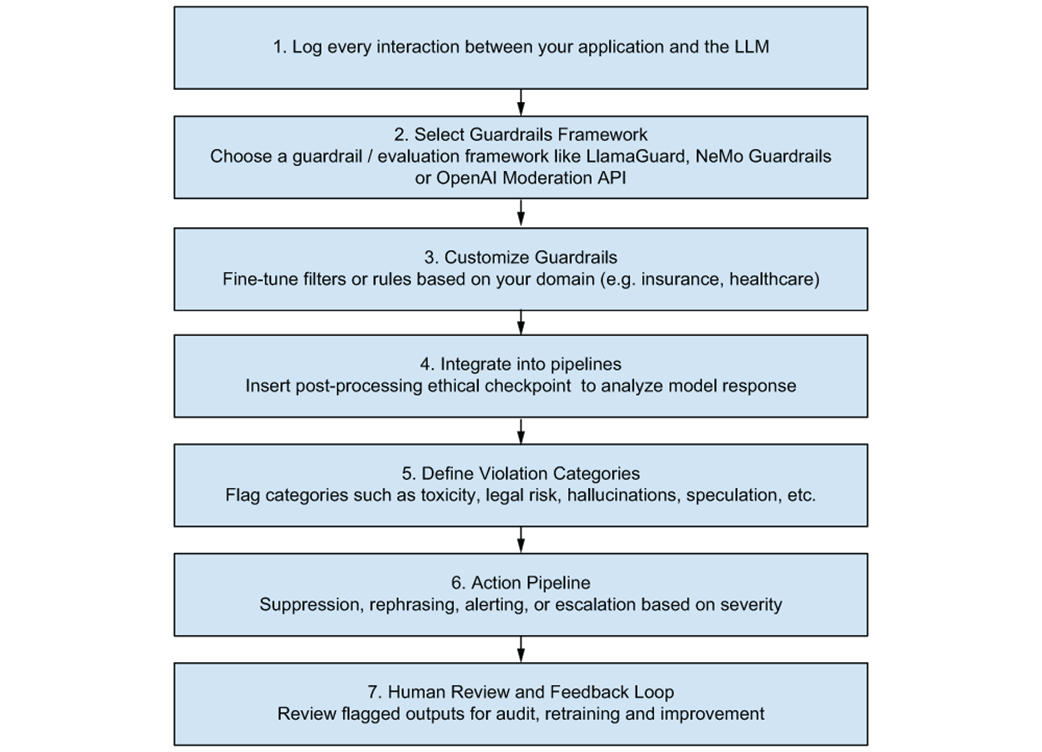
Situates output moderation within a setup workflow that becomes a continuous operational-assurance loop. section 6.5.1
