Moirai is an open-source foundation model for probabilistic time-series forecasting. It produces a distribution of possible future values rather than a single deterministic forecast, supports exogenous features, and is available through a Python package. section 6.1 section 6.5
Its architecture combines patching, an encoder-only transformer, and a mixture of distributions. Patching groups adjacent time steps into tokens, helping the model learn local relationships while reducing the token count and computational burden. section 6.1.1
Figure 6.1 Architecture of Moirai. Here, the series is patched before entering the encoder-only transformer. Then, a mixture of distributions generates a flexible output distribution of future values.
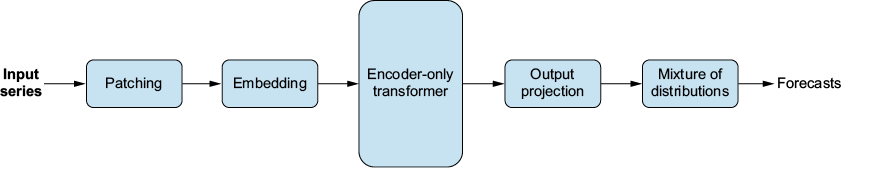
The architecture diagram shows the forecasting path: patch the input series, process patches with an encoder-only transformer, and generate a flexible future distribution. section 6.1.1
Moirai addresses heterogeneous time-series data through several design choices:
- Handles different frequencies, scales, and numbers of variates; the data is flattened into a single series to accommodate arbitrary variate counts. section 6.1.1
- Uses the Large-Scale Open Time Series Archive (LOTSA), containing more than 27 billion data points across energy, transportation, climate, sales, health care, and other domains. section 6.1.2
- Balances frequency coverage during pretraining by subsampling overrepresented series and varies input windows from 2 to 512 time steps. section 6.1.2
- Provides small, base, and large pretrained versions, with 14 million, 91 million, and 311 million parameters respectively. section 6.1.2
A practical workflow installs uni2ts, converts a long-form dataset to GluonTS’s PandasDataset, initializes a pretrained model, creates a predictor, and samples future paths. The median can serve as the point forecast, while percentiles define prediction intervals. section 6.3 section 6.3.1
Weekly sales and anomaly detection
For four Walmart stores, an eight-week zero-shot forecast uses 100 future samples and a 95% prediction interval. Cross-validation with four non-overlapping eight-step windows reports an MAE of 84,140 and sMAPE of 2.64% for the univariate setup; the evaluation notes that available exogenous features were not used. For daily taxi data, values outside the prediction interval are labeled anomalies. One experiment detected all actual anomalies but also produced many false positives, yielding high recall, low precision, and an F1 score of 0.53. section 6.3.1 section 6.3.2 section 6.4
