Multi-agent reinforcement learning coordinates several reinforcement-learning agents that act in parallel within one environment. Each agent can control part of a larger system, enabling more distributed and decentralized control than a single central policy. section 12.4
A mobile-network example assigns one agent to each user's cell-selection task. Five agents operate across stations and users, while shared rewards reflect network performance such as data rate and utility. Ray RLlib wraps the environment, trains the agents with PPO, optionally maps them to one shared policy, and restores the best checkpoint for execution. section 12.4
Coordinating mobile users
Create the mobile-small-ma-v0 environment, register its RLlib wrapper, configure PPO, and assign every agent to shared_policy. During execution, compute one action per agent, step the environment with the action dictionary, and render the changing connections. Training can stop after a configured iteration limit, then select the checkpoint with the highest mean episode reward. section 12.4
Figure 12.10 The mobile-env environment with a number of base stations and user equipment
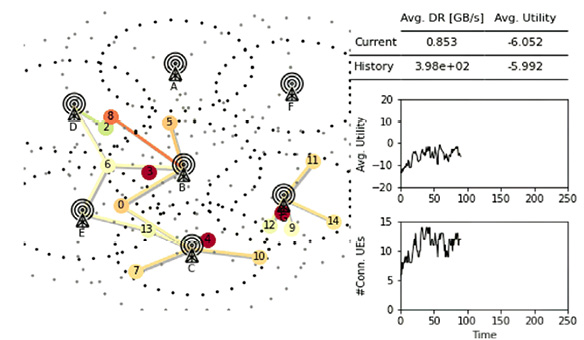
Use the mobile-environment figure to inspect how multiple base stations, users, and dynamically changing connections form a coordination problem. section 12.4
