An n-gram is a contiguous sequence of n items, usually words. Unigrams contain one word, bigrams two, and trigrams three. Counting these sequences in a text corpus lets a language model estimate how likely a word is given the words before it. section 2.3.2
Estimating a next word
If “in the east” occurs 500 times and “in the” occurs 10,000 times, the estimated probability of “east” following “in the” is 5%. A trigram model uses the preceding two words as context. section 2.3.2
Figure 2.2 A visual example of how n grams are extracted from a sentence. Each row shows overlapping windows of different lengths (bigrams, trigrams, and four-grams) sliding across the same sequence of words. As n increases, each unit captures more context, producing progressively larger segments of the original sentence.
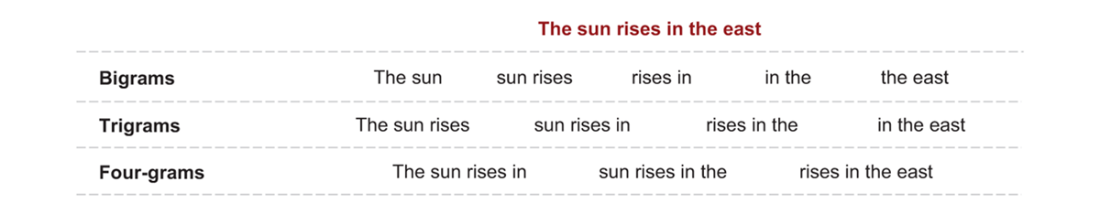
Overlapping windows show how longer n-grams capture more of the surrounding word sequence. section 2.3.2
Increasing n trades broader context for greater estimation difficulty:
- Longer sequences can represent richer patterns, but they occur less often and require more data, storage, and computation. section 2.3.5
- Models may combine n-gram orders and fall back to shorter sequences when longer ones are too rare. section 2.3.5





