An n-gram model estimates the probability of a next word from a fixed number of preceding words. It makes language prediction tractable by approximating the full history with a short local context, an application of the Markov property. The trade-off is that relationships beyond that context are ignored. section 2.3.1
An n-gram is a sequence of n consecutive items, usually words. A bigram contains two words, a trigram three, and so on. A trigram model estimates the next word from the previous two; a four-gram model uses the previous three. The estimates come from counts in a corpus of training texts. section 2.3.2
Figure 2.2 A visual example of how n grams are extracted from a sentence. Each row shows overlapping windows of different lengths (bigrams, trigrams, and four-grams) sliding across the same sequence of words. As n increases, each unit captures more context, producing progressively larger segments of the original sentence.
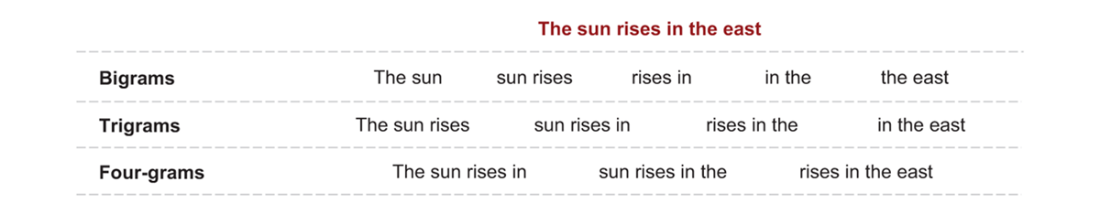
The overlapping windows show how different n-gram lengths capture progressively more context from the same sentence. section 2.3.2
Estimating a next word
Suppose “in the east” appears 500 times in a corpus and “in the” appears 10,000 times. Dividing the first count by the second gives a 5% estimated probability for “east” after “in the.” section 2.3.2
Repeated next-word choices can produce sentences that resemble familiar language patterns. Early probabilistic models achieved this through frequency counts, without hidden grammar rules or an understanding of syntax or meaning. The same statistics supported speech recognition, spelling disambiguation, search, and fluency judgments in machine translation. section 2.3.3
A central difficulty is sparsity: many possible sequences occur rarely or never, even in a large corpus. A model based on raw counts assigns an unseen sequence probability zero, although the sequence may be plausible. Smoothing methods make unseen combinations possible rather than treating them as impossible. section 2.3.4
Approaches to sparse counts include:
- Laplace smoothing assigns a small probability to every possible sequence. section 2.3.4
- Backoff uses shorter contexts when estimates for longer ones are too sparse. section 2.3.4
Increasing n captures longer patterns but also multiplies the combinations that must be estimated. Longer contexts therefore require more data and computation and worsen sparsity. Trigrams became a common practical choice in early speech and natural language processing systems; systems also combined orders, backing off when longer estimates were unavailable. section 2.3.5

