NoPE omits positional encoding from transformer layers, giving attention an unbiased view across the full sequence. It complements position-aware layers by enabling unrestricted global connectivity, especially in extremely long contexts. section 9.5.2
Within the iRoPE design, NoPE serves a specific architectural role:
- Alternates with RoPE layers in a three-to-one RoPE-to-NoPE pattern. section 9.5.2
- Provides global access while RoPE layers preserve fine-grained local and short-range structure. section 9.5.2
- Addresses long-context retrieval challenges, where attention can otherwise distribute probability nearly uniformly across a sequence. section 9.5.2
NoPE in iRoPE
Llama 4’s iRoPE alternates RoPE and NoPE layers to track sentence-level details and document-wide themes across contexts reaching roughly 10 million tokens. section 9.5.2
Figure 9.10 Illustration of the haystack problem. Unmitigated attention (grey) spreads probability mass almost uniformly across the sequence, making it difficult to isolate important tokens. Sharpened attention (black) produces a clear peak at the target position (dashed line), enabling retrieval even within a very long context.
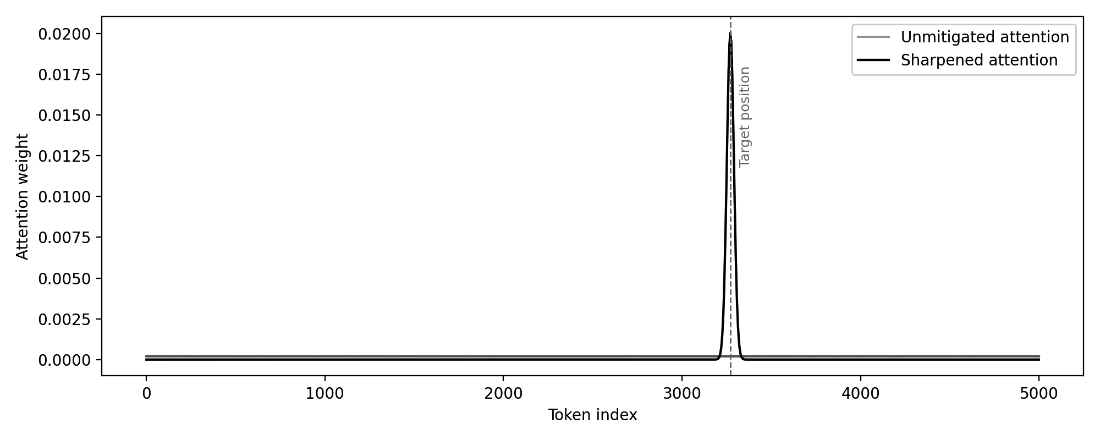
Visualizes the long-context retrieval problem: diffuse attention makes a target token difficult to isolate, while a concentrated distribution enables recovery. section 9.5.2
