Optical character recognition (OCR) extracts written or printed text from images. A production OCR system can identify identity cards in images and extract their ID numbers. section 1.4.2 section 1.1.1
A practical OCR workflow proceeds through these stages:
- Collect images of valid identity cards, including cards from the countries covered by the problem. section 1.1.1
- Annotate the regions containing ID numbers with bounding boxes and transcribe the numbers by hand. section 1.1.1
- Organize labeled data into training, validation, and test datasets. section 1.1.1
- Train an image detector, implement an initial version with an open-source library, fine-tune it with labeled data, and deploy it as a service. section 1.4.2
Identity-card OCR
Given an image containing an identity card, detect the card and its ID-number region, then extract the ID number. If real images are difficult to obtain, consider generating synthetic data before annotation and dataset preparation. section 1.4.2 section 1.1.1
Figure 1.1 The experimentation phase of the ML life cycle
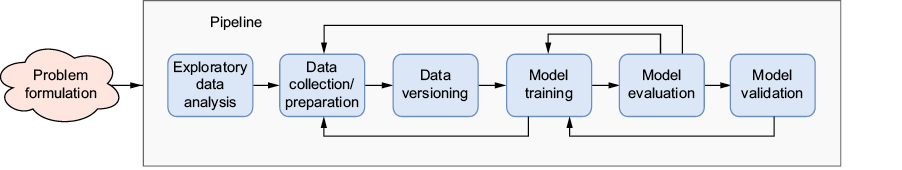
Use the experimentation-phase diagram to place OCR data collection, annotation, training, validation, and testing within the wider ML life cycle. section 1.1.1

