Online DPO addresses a limitation of vanilla DPO: its preference signal comes from completions produced by previous or other models. It samples generations from the current model and incorporates preference signals during training, keeping the optimization loop closer to the model’s evolving behavior. section 8.2
Online preference-optimization variants differ in how they refresh training data:
- Online DPO samples new generations from the current model. section 8.2
- D2PO uses reward-model relabeling to create preference data on the fly. section 8.2
- These online approaches may outperform vanilla DPO, although their exact impact remains uncertain. section 8.2
Figure 8.1 Sketch of preference displacement in DPO
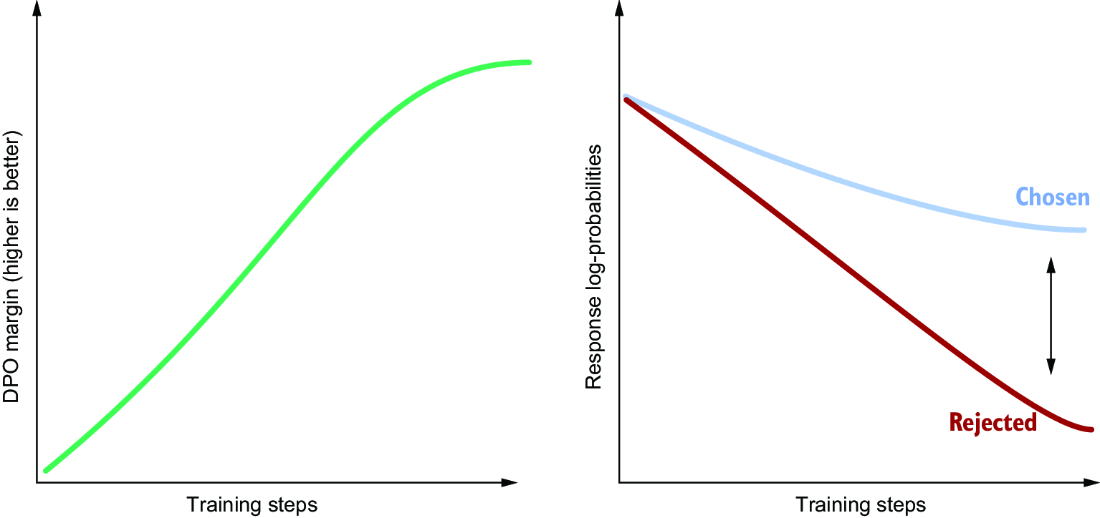
Use the figure to inspect how preference displacement can reduce both chosen and rejected response probabilities, with the rejected response reduced more strongly. section 8.2
