Online learning updates an agent’s knowledge continuously as new information arrives during interaction, rather than waiting for a complete dataset. section 6.1 section 6.7
Business adaptation
A business can adjust prices, inventory, or marketing in real time as live market signals arrive, instead of waiting to analyze a completed period. section 6.1
In reinforcement learning, temporal-difference methods support online updates by correcting estimates step by step from experience. They learn from a next-step estimate rather than waiting for the final outcome. section 6.1 section 6.7
The timing of updates creates a practical trade-off:
- Temporal-difference learning updates quickly but can be short-sighted; Monte Carlo learning waits for episode results and has high variance. section 6.5
Figure 6.7 Comparison of TD(0), Monte Carlo and TD(λ) methods.
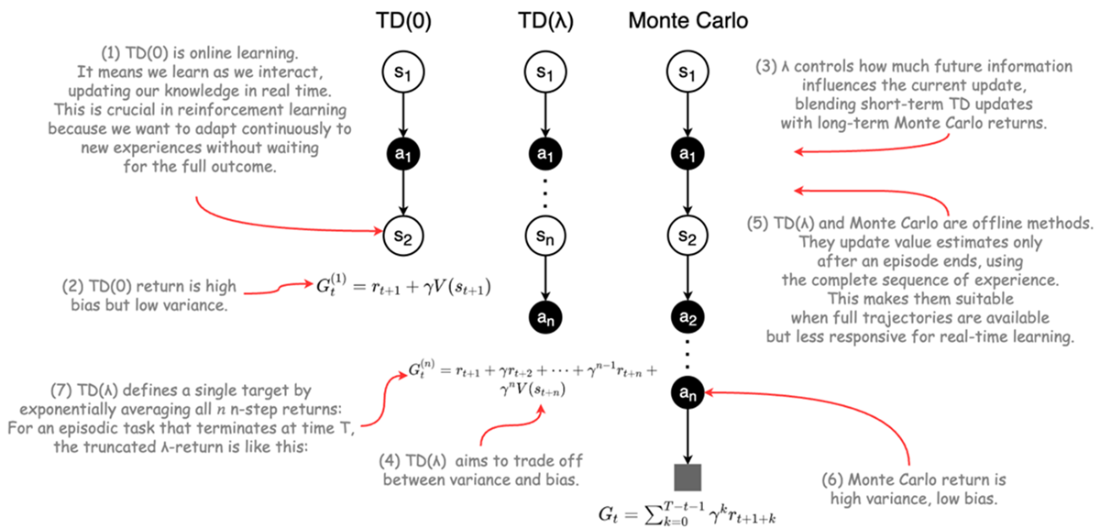
Compare TD(0), Monte Carlo, and TD(λ) as approaches spanning immediate updates and episode-based evaluation. section 6.5

