ONNX Runtime executes ONNX models across platforms, using hardware-specific optimizations to balance deployment flexibility with production performance. section 15.3.1
Use ONNX Runtime when:
- Training and serving use different frameworks, making an interoperable model format valuable. section 15.3.1
- One system must target multiple platforms or hardware backends. section 15.3.1
- You want more performance than directly serving flexible research frameworks, without building a fully custom solution. section 15.3.1
A practical deployment choice
A team can convert models from supported training frameworks to ONNX, then use ONNX Runtime for inference while selecting suitable backends such as OpenVINO for Intel CPUs or TensorRT for CUDA. section 15.3.1
Figure 15.3 A wide spectrum of tools with their focus on either research or production serving goals
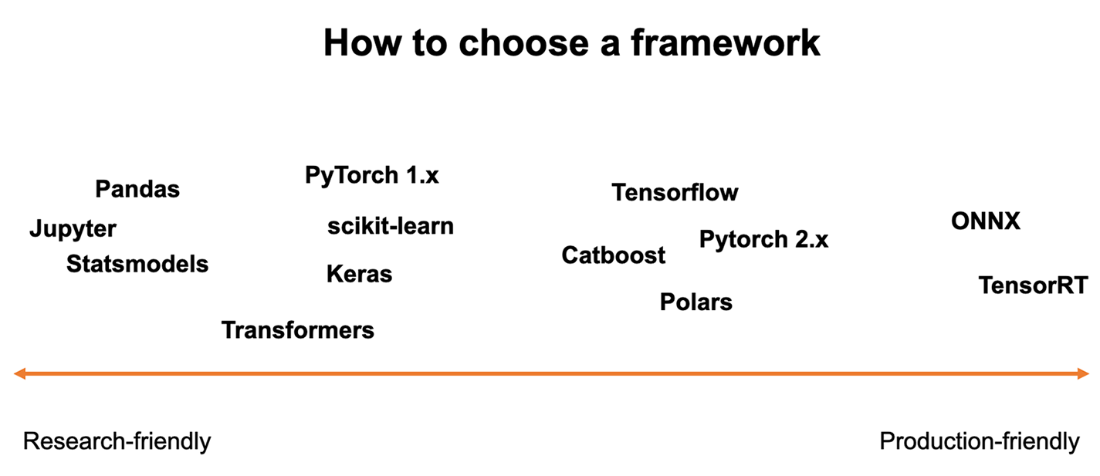
Compare ONNX Runtime with tools positioned closer to research flexibility or production-serving specialization. section 15.3.1


