OpenAIEmbeddings converts supplied text into vectors of numbers so a vector database can store and compare its meaning. In a RAG workflow, it prepares document chunks for storage and user queries for similarity search. section 4.2
A practical embedding workflow has three stages:
- Split source documents into chunks, then send the chunks through OpenAIEmbeddings before storing them in ChromaDB. section 4.2
- Convert each user query with the same embedding model so the vector database can find relevant chunks by similarity. section 4.2
- Choose a model size deliberately: larger models create longer vectors and may describe chunks better, but cost more. section 4.2
Figure 4.14 The document ingestion subflow is ready.
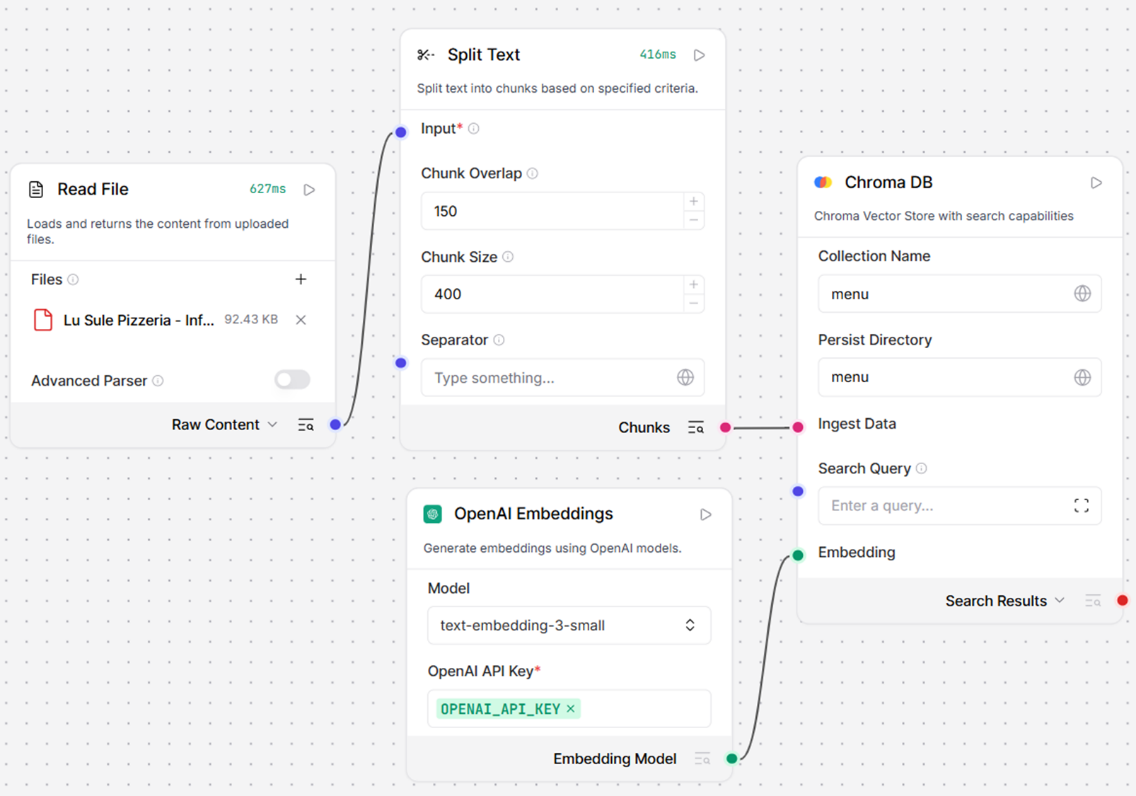
The ingestion-flow diagram shows OpenAIEmbeddings connected between document chunks and ChromaDB. section 4.2

