Optax is a JAX-based library for gradient transformations and optimizer-building blocks. It supplies ready-to-use optimizers and a composable framework for creating custom update rules from reusable pieces. section 11.1.2 section 12.1.3
The practical role of Optax here is to simplify training loops: create an optimizer, initialize its state, turn gradients into updates, and apply those updates to model parameters. In the surrounding workflow, it plugs into TrainState to hide most of that boilerplate. section 11.1.2 section 11.1.3
Optax is tied here to a small set of recurring ideas:
- gradient transformations and reusable optimizer pieces. section 11.1.2
- TrainState for storing optimizer state and applying gradients. section 11.1.3
- JAX training loops and functional model updates. section 11.4
Using an Optax optimizer in a training step
An example workflow creates an Adam or SGD optimizer, initializes state from model parameters, computes gradients with jax.grad or jax.value_and_grad, then calls optimizer.update() and applies the resulting parameter updates. A TrainState-based loop hides the state initialization and update application inside apply_gradients(). section 11.1.2 section 11.1.3
Figure 11.2 The process of using an optimizer in Optax (only a single gradient update step is shown)
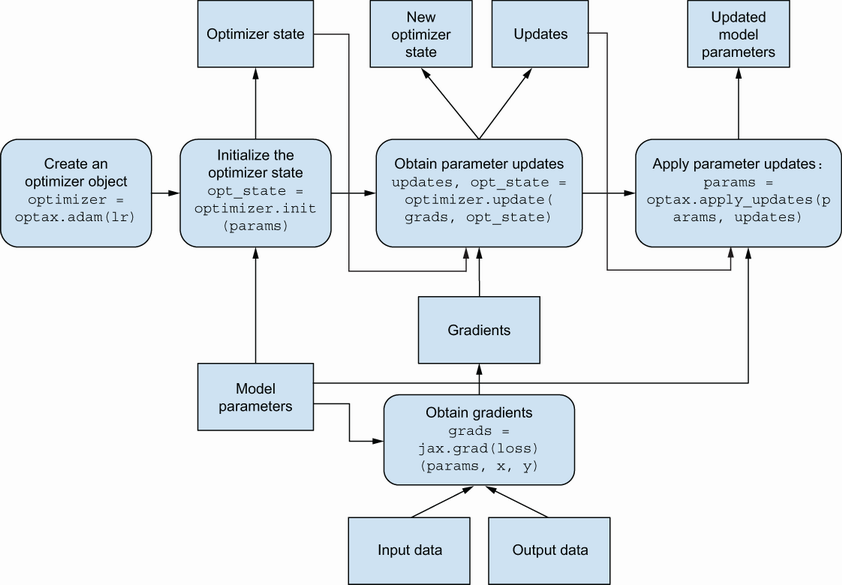
Shows the one-step optimizer flow from gradient computation to parameter updates. section 11.1.2
