A paged optimizer manages optimizer memory in pages during fine-tuning. It addresses memory spikes, especially those caused by gradient checkpointing, by dynamically moving data between CPU and GPU memory. section 8.3.4
Within QLoRA, paging complements low-bit model storage, double quantization, and low-memory adaptation. Instead of requiring all optimizer state to remain on the GPU, the implementation allocates and transfers memory as training demands change, helping avoid out-of-memory failures under tight hardware limits. section 8.3.4 section 8.3.5
Paged optimizers are useful when:
- Gradient checkpointing creates temporary memory spikes that can exceed available GPU capacity. section 8.3.4
- Fine-tuning must run with the minimum practical number of GPUs. section 8.3.5
- Optimizer data must move efficiently between CPU and GPU memory while training continues. section 8.3.4
Figure 8.14 Overview of fine-tuning methods: on the left is the usual fine-tuning, without any optimization; in the middle, LoRA; and on the right, QLoRA. Image is taken from [6].
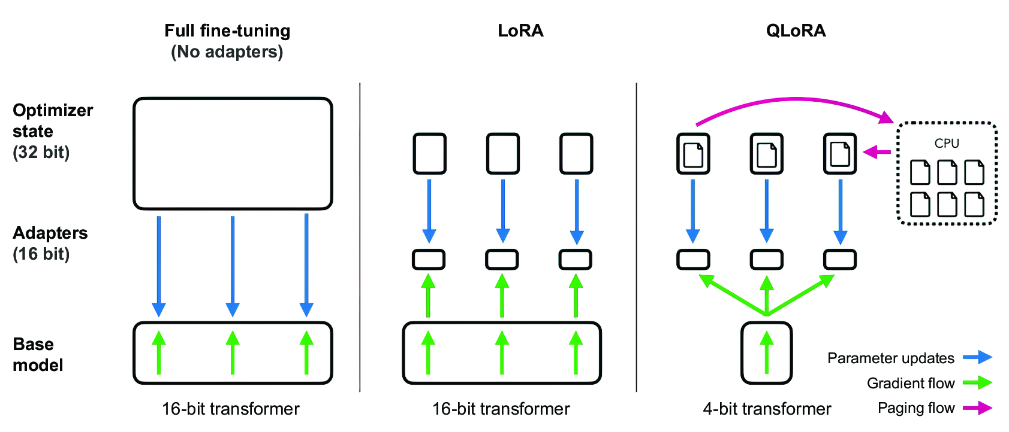
Compare ordinary fine-tuning, LoRA, and QLoRA to see where paged optimization fits within progressively more memory-efficient adaptation strategies. section 8.3.4
