Paired testing checks whether a system treats matched scenarios differently when one selected characteristic changes. For LLM fairness tests, teams vary a sensitive signal while keeping the rest of the scenario comparable, then compare the system’s outcomes. section 6.2.3
A repeatable test loop can:
- Select critical journeys such as denials, escalations, fraud flags, or summaries. section 6.2.3
- Capture each prompt variant, the changed attribute, an outcome label, and agreed indicators such as tone or bias. section 6.2.3
- Compare group outcome rates, investigate disparities, and rerun tests after changes. CI jobs can block releases when metrics cross warning thresholds. section 6.2.3
- Use observed unfair responses to create corrected pairs for fine-tuning or prompt refinement, then retest fairness and accuracy. section 6.2.4
Claim decisions
For the same claim type, change one sensitive signal and compare outcomes such as approve, deny, or escalate. A higher denial rate for one group warrants investigation; the result depends on choosing relevant scenarios and groups. section 6.2.3
Figure 6.5 Bias Testing Workflow for LLMs. A step-by-step process: generate prompts, collect LLM outputs, structure data, and analyze for bias using fairness toolkits.
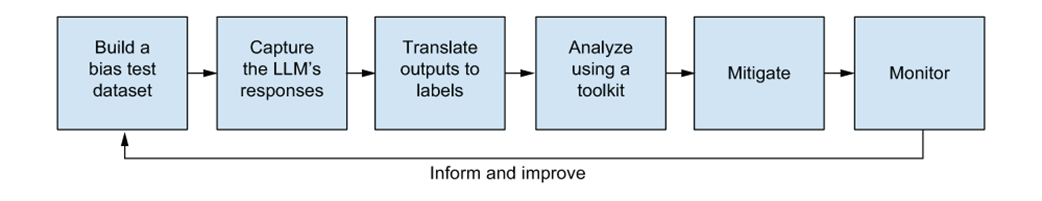
Follow the workflow from generating prompts and collecting outputs to structuring results and analyzing them with fairness toolkits. section 6.2.3
