Policy iteration is an iterative reinforcement-learning method that alternates between evaluating a policy and improving it until convergence. It seeks an optimal policy that maximizes expected cumulative discounted reward, alongside value iteration and policy gradients. section 12.1.2
The method connects policy choices with value functions: the state-value function estimates expected future reward from a state under a policy, while the discount factor controls the importance of later rewards. section 12.1.2
Figure 12.4 Reach the Treasure game
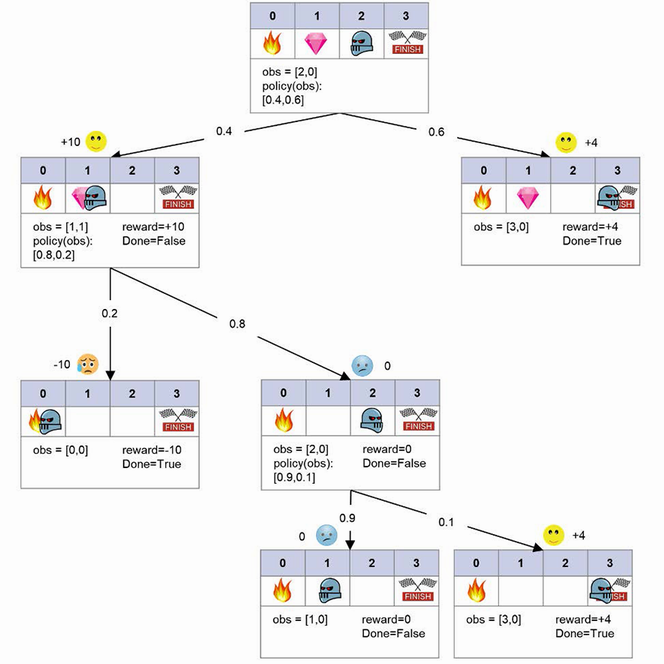
Use the Reach the Treasure game as a compact reinforcement-learning setting for relating policies, trajectories, and expected returns. section 12.1.2
