In reinforcement learning from human feedback (RLHF), the policy model is the trainable copy of a supervised fine-tuning model. It generates a response token by token, receives a score from the reward model, and updates its response probabilities through PPO. section 10.7
Medical chatbot
For a chest-pain prompt, the policy can learn to favor a response that acknowledges concern, avoids diagnosis, recommends medical evaluation, and escalates severe symptoms over one that only lists possible causes. section 10.7
Figure 10.6 Reinforcement Learning from Human Feedback with PPO.
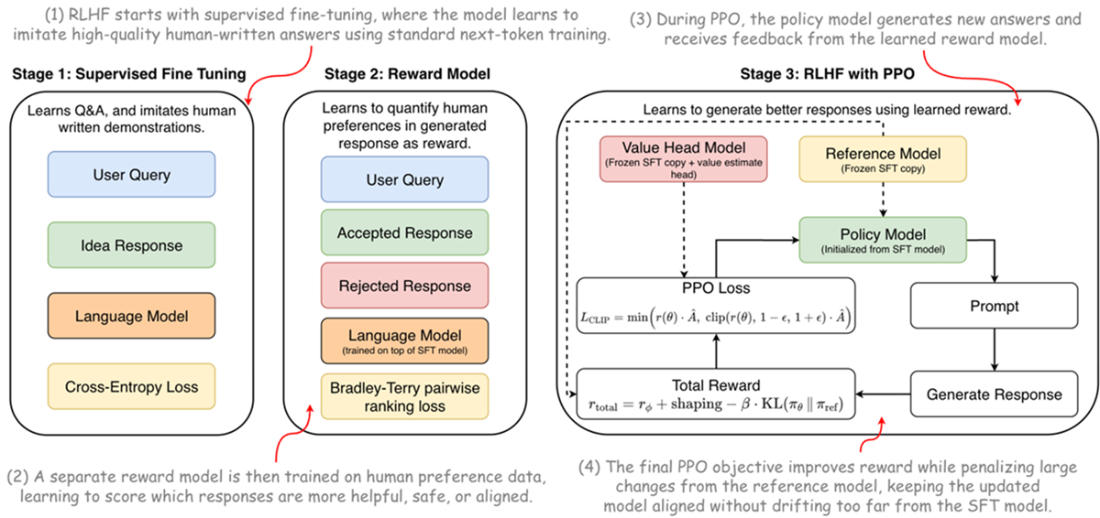
The pipeline places the policy model in the RLHF stage, after supervised fine-tuning and reward modeling. section 10.7
