PPO-penalty is a proximal policy optimization variant that limits how far an updated policy moves from the policy that collected the data. This protects learning from unstable updates that make advantage estimates inaccurate and can severely disrupt the policy. section 12.1.5
Its update follows a trust-region idea:
- Adds a penalty for divergence between the updated policy and the old policy to the objective. section 12.1.5
- Measures divergence with Kullback–Leibler (KL) divergence, which quantifies dissimilarity between probability distributions. section 12.1.5
- Uses the penalty coefficient β and optimizes the resulting unconstrained objective with stochastic gradient ascent. section 12.1.5
KL divergence between two Gaussian distributions
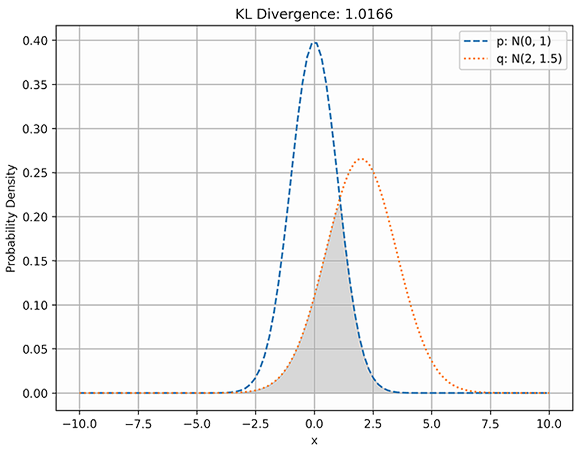
Compare KL divergence between two Gaussian distributions to build intuition for how policy dissimilarity is measured. section 12.1.5
