A predictor backend client represents one backend predictor and connects the frontend service to it. It manages backend communication and can transfer model files before forwarding prediction requests. section 7.1.3 section 7.2.3
A backend client participates in the serving workflow by:
- Implementing model operations such as downloadModel, registerModel, and predict. section 7.1.3
- Receiving the selected model metadata and checking or downloading its files to shared storage. section 7.1.3
- Sending the model run ID and document to the registered predictor through a gRPC stub. section 7.1.3
- Supporting multiple backend technologies by registering clients under model algorithm types. section 7.1.3 section 7.2.3
Intent classification with a custom gRPC backend
A request for model A reaches the web interface, which obtains metadata and asks the predictor connection manager to select the client for the model algorithm. CustomGrpcPredictorBackend downloads the model if necessary, invokes the registered intent predictor, and returns its response. section 7.1.3
Adding a TorchServe client
Register TorchGrpcPredictorBackend for models whose metadata names TorchServe. The client downloads model files and sends prediction requests to the TorchServe container. section 7.2.3
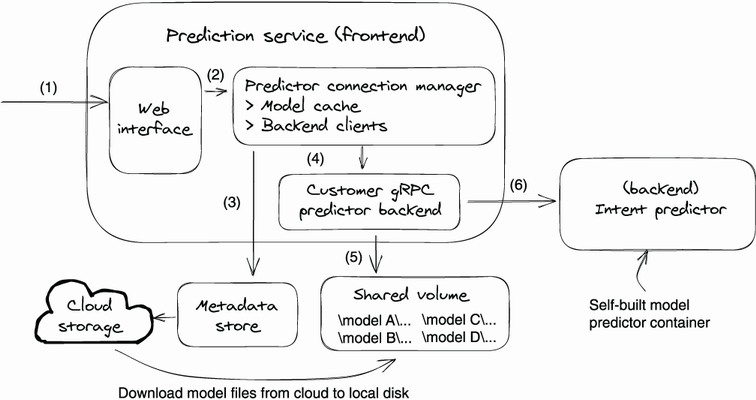
Use the workflow diagram to trace request routing, metadata lookup, backend selection, model transfer, and prediction communication. section 7.1.3
