PyIceberg is the native Apache Iceberg Python library for programmatic table access. It lets notebooks and machine learning pipelines read and write Iceberg tables directly, reducing extra ETL steps between curated data and Python workflows. section 4.5.1
Its architectural value is lightweight, direct access. A small team can combine PyIceberg with the Hadoop catalog and filesystem paths to create and manage Iceberg tables in Amazon S3 without deploying additional catalog services. This reduces operational overhead while preserving the option to migrate later to REST or enterprise catalogs without changing table layouts. section 7.5.8
Common deployment patterns include:
- Developer laptops run Python scripts for transformations and metadata operations against Iceberg data stored in S3. section 7.5.8
- JupyterLab integrates PyIceberg with DuckDB for SQL queries and Arrow-backed in-memory dataframes. section 9.5.1
- Catalog-based reads and Iceberg snapshots support dataset discovery, security enforcement, and reproducible training workflows. section 9.5.1
Figure 4.6 The Hamerliva Bank architectural proposal shows how the components relate to one another.
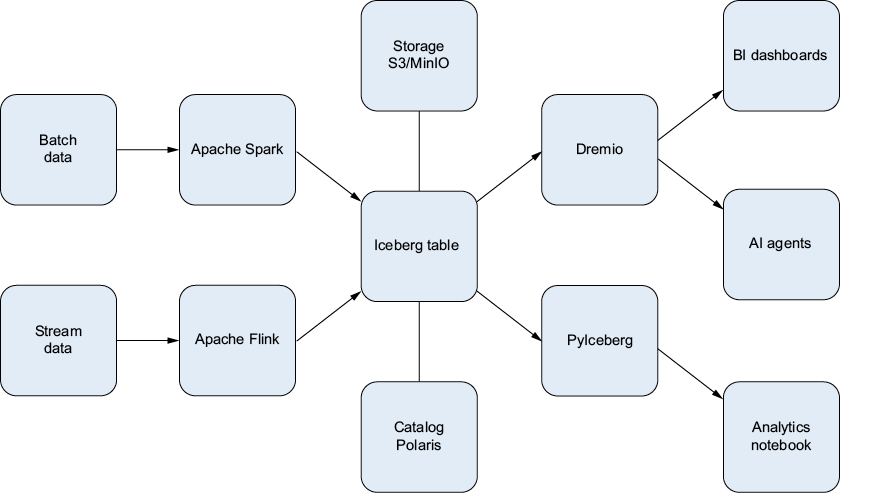
Use the architecture proposal to see how PyIceberg connects Python notebooks and machine learning pipelines to governed Iceberg datasets. section 4.5.1
