QLoRA combines low-rank adaptation with quantization to reduce the memory and computation required to fine-tune large language models. It quantizes low-rank matrices while preserving the pretrained model weights, enabling efficient specialization without full-model updates. section 9.6.1
The technique provides several practical trade-offs:
- Reduces trainable parameters and can achieve up to 99% parameter reduction through an 8-bit optimizer for quantization. section 9.6.1
- Uses lower-precision representations, such as 8-bit or 4-bit values, to reduce model memory and potentially speed inference. section 9.6.1
- Trades some potential accuracy for efficiency because reduced numerical precision can affect model accuracy. section 9.6.1
Figure 9.14 LoRA reparameterization—only A and B are trained [9]
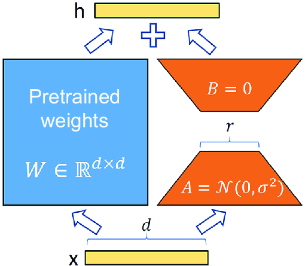
Inspect the LoRA reparameterization diagram to see how adaptation trains only the low-rank matrices A and B; QLoRA further quantizes those matrices. section 9.6.1


