A query strategy selects unlabeled training examples for labeling in active learning. It prioritizes examples expected to provide the most useful information. section 7.3.1
Common criteria include:
- Uncertainty sampling queries least-certain predictions: points near a binary decision boundary, low-margin or high-entropy multiclass predictions, and high-variance regression predictions. section 7.3.1
- Query by committee maintains competing models and selects candidates on which their label predictions disagree most. section 7.3.1
Logistic-regression active learner
An implementation ranks an unlabeled pool with least-confidence, max-margin, entropy, vote-entropy, or average-KL-divergence strategies, then queries a selected number of examples. A synthetic two-class logistic-regression experiment compares active selection with random sampling.
Figure 7.11 Uncertainty sampling techniques comparison. The left figure shows that active learning is better than random sampling. The right figure shows that average KL divergence is better than random sampling.
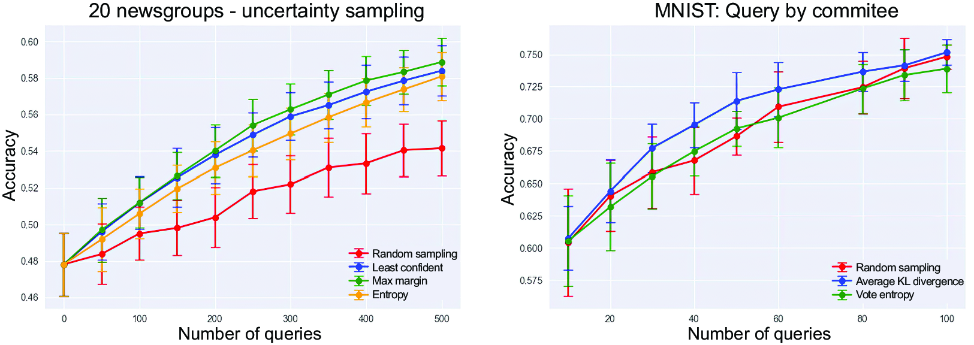
Compare uncertainty-sampling techniques with random sampling and inspect reported performance differences. section 7.3.1
