Imagine building many image classifiers, each seeing a different set of images and pixels. Random patches creates this diversity by independently sampling both training examples and input features for every base estimator. section 2.4.2 section 2.0
Build a random-patches ensemble procedurally:
- Choose a base learner, such as an SVC; the method is not restricted to decision trees. section 2.4.2
- For each estimator, sample a subset of training examples and a subset of features, with or without replacement. section 2.4.2
- Train the learner on its sampled rows and columns, then aggregate predictions across the independently trained estimators. section 2.0 section 2.6
A scikit-learn configuration
Use BaggingClassifier with max_samples=0.75 and bootstrap=True for example sampling, plus max_features=0.5 and bootstrap_features=True for feature sampling. Sampling features can make learners more efficient on image or text data with many dimensions. section 2.4.2
Figure 2.9 Bagging compared to random subspaces and random patches. The unshaded rows and columns represent training examples and features, respectively, that have been left out.
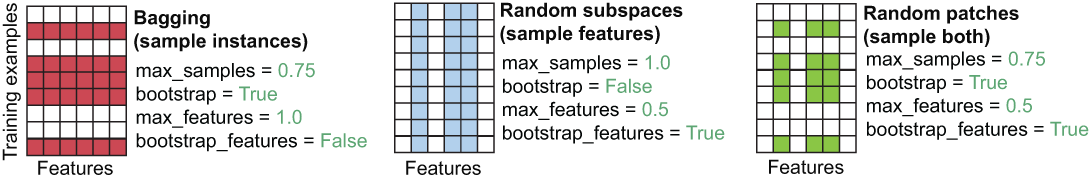
Compare which rows and columns remain available to bagging, random subspaces, and random patches. section 2.4.2
Unlike random forests, random patches samples features once before each base learner runs; random forests sample features inside randomized decision-tree growth. section 2.4.2

