liveBook · Manning

Ray RLlib

As explained in Optimization Algorithms: AI techniques for design, planning, and control problems

Ray RLlib is an open-source reinforcement-learning library for scalable and distributed training with unified APIs.

Ray RLlib is an open-source reinforcement-learning library for production-level, highly distributed workloads. It keeps APIs unified and simple while supporting industry applications such as decentralized mobile-network coordination. section 12.4

A practical RLlib workflow includes:

  • Install Ray RLlib with pip and register a wrapped Gymnasium environment. section 12.4
  • Initialize Ray, configure PPO, allocate rollout workers, and define shared or mapped multi-agent policies. section 12.4
  • Train with Ray Tune, stop after a chosen iteration limit, checkpoint the result, and select the highest-reward run. section 12.4
  • Restore the checkpoint, compute actions for each agent, evaluate the environment, and render coordination results. section 12.4

Multi-agent mobile-network coordination

Five agents control cell selection for five users across three stations in a small mobile environment. PPO trains the shared policy, and evaluation renders the resulting connections, average data rate, and utility. section 12.4

Figure 12.11 Coordination of the mobile environment using a multi-agent PPO
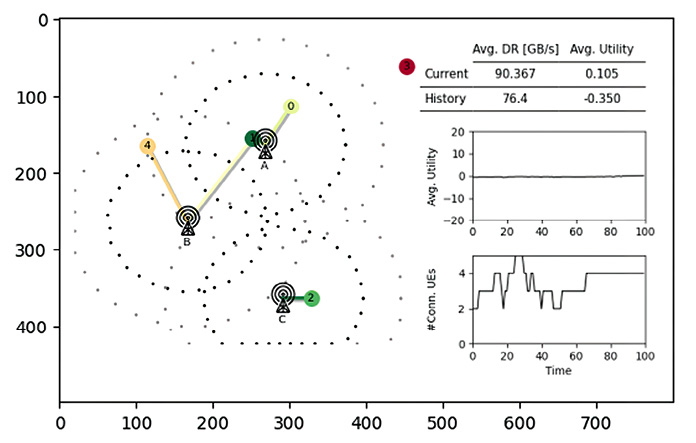
Use the rendered coordination figure to inspect how the trained multi-agent policy connects users with base stations. section 12.4

How Optimization Algorithms: AI techniques for design, planning, and control problems covers it

How deep it goes
Descends through environment wrapping, Ray setup, PPO configuration, training, checkpoint selection, restoration, and evaluation.
Examples
Uses a five-user, three-station mobile environment with shared-policy multi-agent PPO and rendered evaluation.
What it assumes
Assumes familiarity with Python environments and reinforcement-learning concepts while demonstrating the distributed setup from configuration onward.
What you can do after
Build and evaluate a multi-agent PPO training pipeline with Ray RLlib, checkpoints, rollout workers, and rendered results.
How it connects
Connects reinforcement learning, multi-agent reinforcement learning, PPO, Gymnasium, Ray, and Ray Tune.

This explainer was generated by Manning's knowledge graph from the text of Optimization Algorithms: AI techniques for design, planning, and control problems. The section links point to the parts of the book it draws on.