Imagine several workers counting words in separate stacks of pages. A reduce task gathers their intermediate key-value pairs and combines the values belonging to each unique key, turning repeated partial results into final totals. section 13.10
A reduce phase follows a simple handoff:
- Receive the map output as key-value pairs. section 13.10
- Group values associated with each unique key. section 13.14
- Call the reduction function for each key and write the final output. section 13.14
Counting words
If mapping produces [("the", 1), ("take", 1), ("the", 1)], reduction combines the two values for "the" and returns [("the", 2)]. A larger implementation can assign word lists to reduce tasks, while the scheduler starts reduction after all map tasks finish. section 13.10 section 13.13
In a concurrent pipeline, workers process intermediate data, invoke reducefn once per unique key, and write results to a file. The scheduler uses distinct mapping, reducing, and finished states; the implementation uses one workflow for its single reduce task. section 13.14
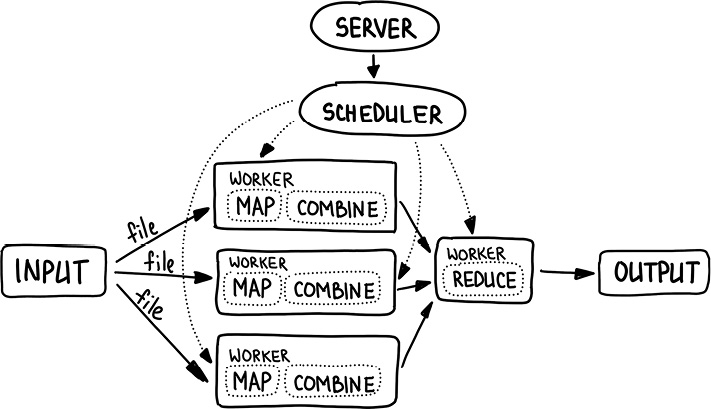
Use the program overview to trace how map outputs flow through scheduling into the reduce phase. section 13.14
