Regret answers a causal, retrospective question: how much better or worse would the outcome have been if a rejected action had been chosen? It compares the realized utility or reward with an imagined counterfactual outcome. Negative regret means the rejected option would have performed better; positive regret means the chosen option was better. section 8.1.4 section 12.6.2
The comparison supplies more information than the observed decision alone. A decision produces one outcome, while a sufficiently accurate counterfactual estimate provides a second point for learning. Because counterfactual outcomes are uncertain, probability distributions can represent that uncertainty. section 8.1.4
Estimating missed in-game purchases
Suppose a player with low engagement spent $50. If counterfactual inference samples the purchases they might have made under high engagement, define regret as RE = IE − 50. Averaging those sampled differences estimates expected regret. The same pattern compares recommendation policies by contrasting observed purchases with purchases expected under an alternative policy. section 9.1.4
Regret supports several decision workflows:
- Backtest alternative investment allocations against the realized portfolio outcome. section 8.1.4
- Simulate alternative policies in saved game instances and use the outcome differences to improve reinforcement-learning policies. section 8.1.5
- Minimize cumulative regret by selecting policies that would have produced higher rewards across logged contexts. section 12.6.2
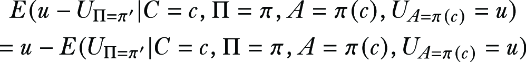
Trace the decision structure from context to policy, action, realized reward, alternative policy, and counterfactual reward. section 12.6.2


