Reinforcement Learning with Verifiable Rewards (RLVR) trains a language model using a program that checks whether its answer is correct. When a task has an objective answer, this avoids learning a separate reward model to approximate human preferences. section 11.0 section 11.2
Scoring a financial answer
For a financial-report question, a Python verifier extracts the final number, parses it, and compares it with the gold answer using a small relative tolerance. Correctness earns 1.0; a boxed answer earns an additional 0.1, even when incorrect. section 11.2
The verifier assigns four possible scores:
- 1.1 for a correct, boxed answer. section 11.2
- 1.0 for a correct, unboxed answer. section 11.2
- 0.1 for an incorrect, boxed answer. section 11.2
- 0.0 for an incorrect, unboxed answer. section 11.2
Feedback arrives only after the model produces its final answer, not after each reasoning token. Requiring a boxed answer makes that result easy to locate; the separate format bonus distinguishes a well-formatted attempt from one that omits the expected format. section 11.1 section 11.2
Figure 11.1 FinQA financial question answering as a language-model RL environment.
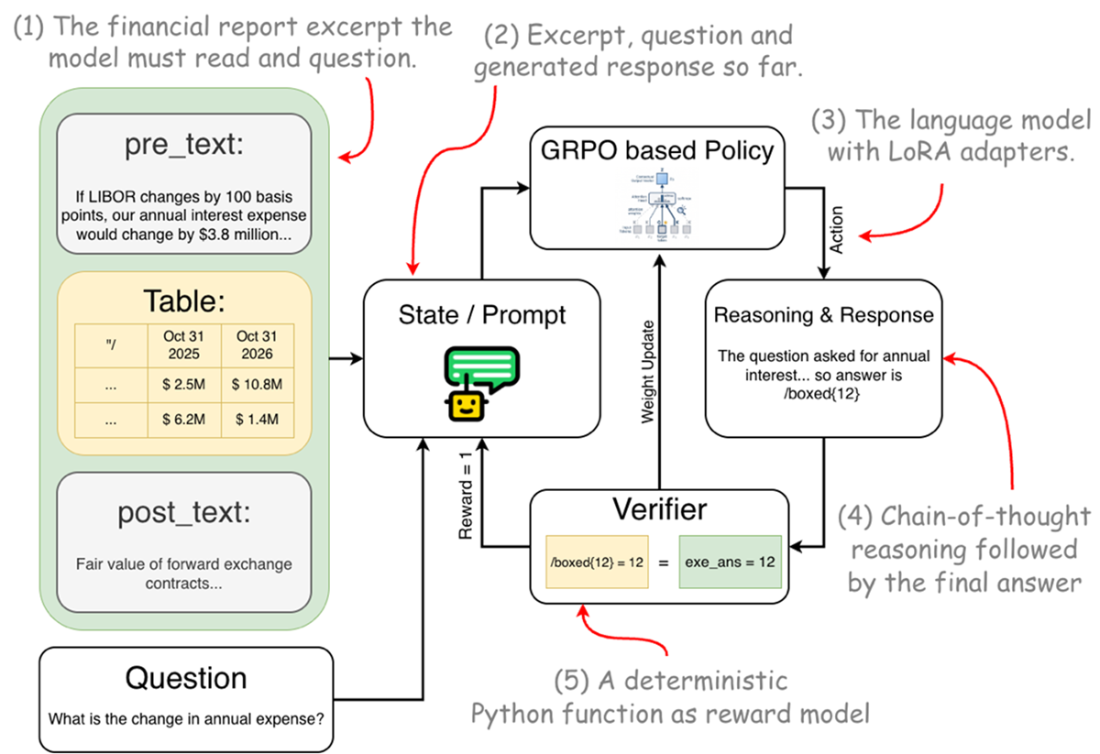
See the financial question-answering task represented as a language-model reinforcement-learning environment. section 11.1
RLVR fits tasks with objectively checkable answers, especially when solving them requires multi-step reasoning. It is less suited to answers based mainly on taste or preference, where no single correct response can be verified. section 11.0 section 11.9





