A repartition topic is an internal Kafka topic that temporarily redistributes records after their key changes. Kafka Streams writes records to a topic ending in -repartition, then reads them back so joins and aggregations can run on the correct key. This increases network traffic and storage requirements but preserves keyed-processing correctness. section 12.6 section 12.7
Changing the key before counting
A topology that calls selectKey() and then count() cannot continue as one processing segment. Kafka Streams writes the newly keyed records to the repartition topic, then reads them in a second subtopology for aggregation. Likewise, groupBy((key, value) -> newKey) changes the key, creates a repartitioning topic, and groups records by that new key. section 12.6 section 12.4.2
A repartition topic matters because it:
- Routes records to processing tasks according to their current key. section 12.6
- Separates processing into subtopologies because Kafka Streams cannot write to and read from the topic within one task. section 12.6
- Supports correct joins and aggregations after repartitioning, at the cost of additional network traffic and storage. section 12.6
Figure 12.14 If we first execute a selectKey() and then an aggregation such as count(), the topology needs to be split up into multiple subtopologies.
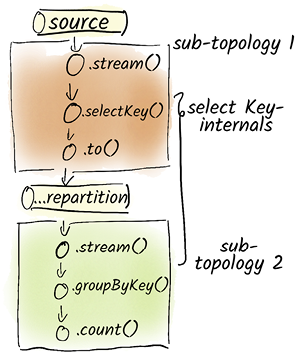
Use the topology figure to see why selectKey() followed by an aggregation creates multiple subtopologies. section 12.6

