A retrieval metric quantifies whether an information-retrieval component returns relevant, sufficient documents for a downstream task. In RAG, this separates retrieval failures from generation failures: faithful answers can still summarize irrelevant context, while inadequate retrieval can cause hallucination. section 6.1 section 6.2
Choose metrics according to the failure being investigated:
- Precision and recall measure whether the right documents were retrieved. section 6.5
- Precision@k, MRR, MAP, and nDCG penalize relevant documents ranked below the context-window cutoff. section 6.5
- RAGAS context recall tests whether retrieved context covers the ground-truth answer, while context precision tests relevance and ranking above noise. section 6.5
- Interpret scores alongside retrieval methods: lexical search misses variation, BM25/TF-IDF misses paraphrase, and dense search can miss precise identifiers. section 6.5
Diagnosing a RAG failure
If context recall is low while faithfulness is high, the system likely has a retrieval gap: the model uses retrieved information faithfully, but the retrieved context does not cover the answer. Diagnose the gap against the retrieval method's known failure mode before changing generation. section 6.5
Figure 6.1 The basic single-turn Retrieval-Augmented Generation architecture. A user question is routed to a retrieval system, which queries a knowledge base and returns relevant documents. The LLM synthesizes an answer to the question and retrieves context, producing responses supported by sources.
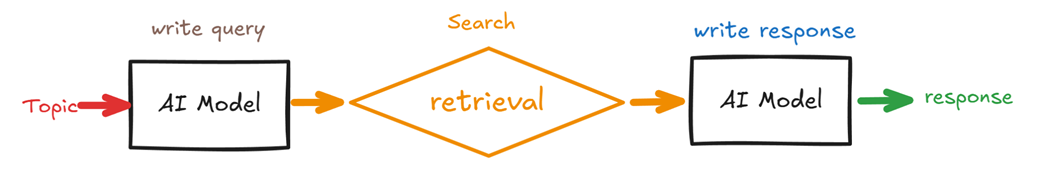
Trace how a user question becomes retrieved context and then a generated answer; this makes the boundary between retrieval quality and generation quality concrete. section 6.1


