Retrieve and answer is the runtime half of a retrieval-augmented generation (RAG) system. It searches a vector database for chunks relevant to a user question, combines those chunks with the query, and invokes a language model to produce an answer. section 4.2
The workflow runs in three practical steps:
- Accept a user query. section 4.2
- Run vector similarity search to retrieve the most relevant embedded document chunks. section 4.2
- Pass the query and retrieved text to an LLM to generate the answer. section 4.2
Pizza assistant
A virtual assistant can answer questions about a pizzeria’s PDF menu, such as prices or wine pairings, by retrieving relevant menu chunks before generating its response. section 4.2
Figure 4.15 A simplified sketch of our retrieve and answer subflow
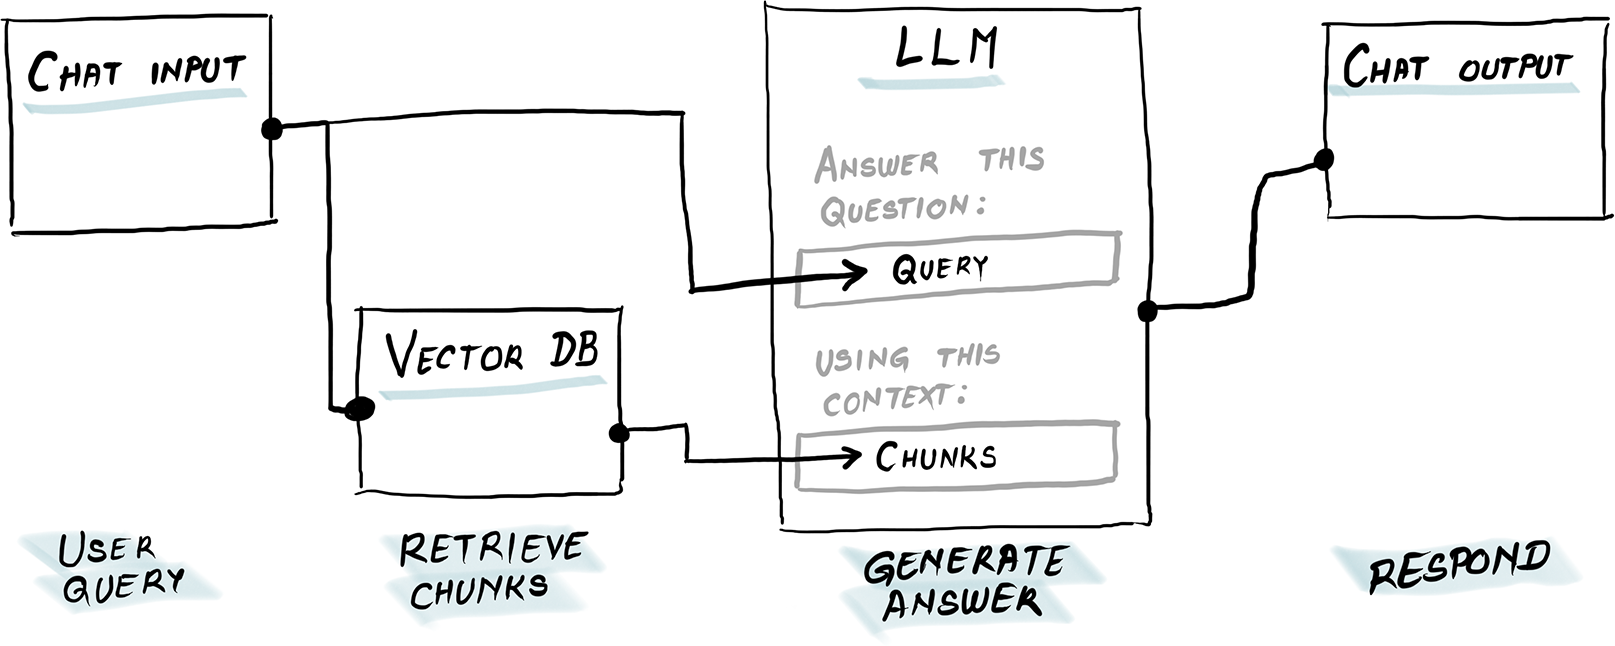
Use the simplified subflow sketch to see how a query moves from retrieval to answer generation. section 4.2
