A row group is a horizontal partition of rows stored and processed as a unit in Parquet or DuckDB storage. Each partition shares the table schema and contains information for every column. section 5.4 section 10.2.2
Row-group sizing balances compression, metadata overhead, and parallel reads. Smaller groups compress less effectively and require more headers; oversized groups limit DuckDB’s ability to parallelize reading. section 5.4
Choose a row-group size during conversion
DuckDB can write a joined ATP rankings dataset to Parquet with an explicit size: COPY (...) TO 'atp_rankings.parquet' (FORMAT PARQUET, CODEC 'SNAPPY', ROW_GROUP_SIZE 100000). The resulting file is 36M, while metadata reports 20,726 rows in its first row group when the source is written with a different configuration. section 5.4 section 5.5
Parquet metadata records statistics per row group and column. A query filtering ranking_date after 1980 can skip a group whose maximum date is 1979, avoiding unnecessary value reads. section 5.5
Figure 10.4 Morsel runtime
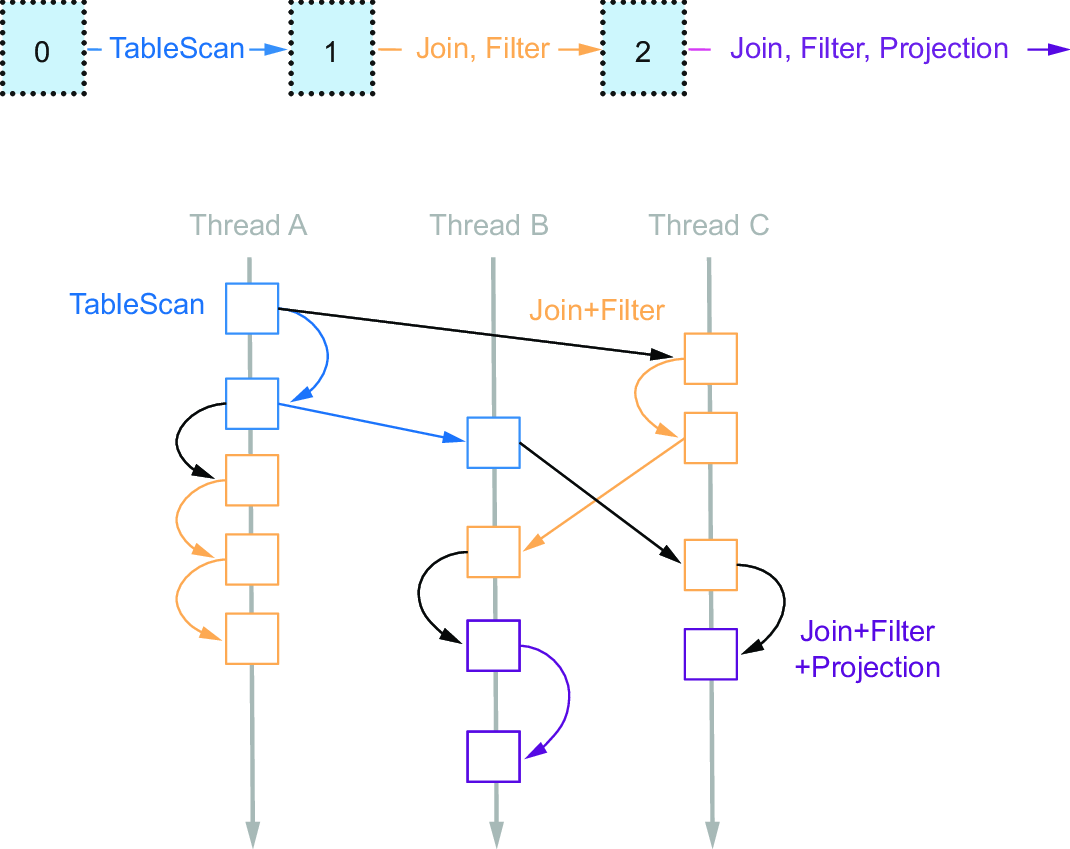
The morsel-runtime figure shows how row-group data feeds chunked, parallel execution pipelines. section 10.2.2


