Shared weight means reusing the same learned weight matrices across multiple positions or computation steps. In an RNN, one set of matrices is applied to every token, while hidden states and outputs pass from one step to the next. section 8.3
This reuse reduces the model’s distinct parameters but makes training dependent across time. Backpropagation through time must propagate each token’s error backward through every earlier use of the shared matrices, serially. section 8.3
Shared matrices in an unrolled RNN
For a text sequence, the RNN applies the same weight matrices to token 1, token 2, and later tokens. After comparing the final output with the correct label, training works backward through those repeated applications and adjusts the shared weights using each token’s error. section 8.3
Figure 8.10 Data fed into a recurrent network
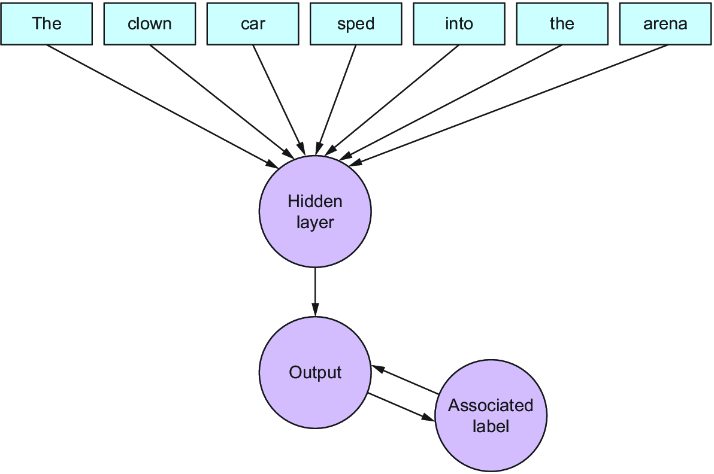
Trace how token inputs, hidden states, and recurrent computations are arranged across time. section 8.3

