Model inference means applying a trained model to an input to produce an output. In a voice assistant, it is the step that turns transcribed speech into an AI response. Ollama runs the language model locally, so the prompt and response can stay on your Mac. section 1.0 section 10.9
Follow one spoken request through the application:
- The browser captures audio; MLX Whisper transcribes it into text. section 10.9
- The text reaches the same message handler used for typed input. Ollama performs LLM inference and streams the response. section 10.9
Local inference can work without an internet connection after the model has been downloaded. That reduces the need to transmit prompts and responses, though privacy still depends on the rest of the application and its configuration. Inference need not run on the same device as the interface: a small agent can handle messages while an LLM API or an Ollama server on a larger machine runs the model. section 14.6 section 16.5.5
Figure 16.3 The architectural contrast between OpenClaw and PicoClaw: a full-featured agent and an ultra-lightweight agent, both connecting to LLM backends
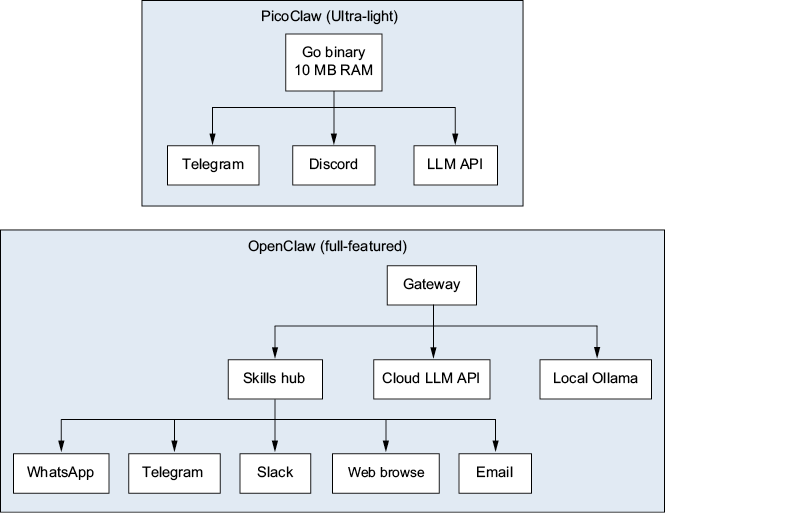
Compare agent runtimes that connect to LLM backends rather than performing model inference themselves. section 16.5.5
