A small file is a data file whose low size makes file-opening, read coordination, scheduling, and metadata costs significant relative to its contents. Streaming and micro-batch pipelines commonly create many small Parquet files through frequent commits. section 10.1.1
Small files create several operational effects:
- Increase file enumeration, object-store API calls, and read scheduling, potentially making fixed costs dominate query execution before bandwidth becomes a bottleneck. section 10.1.1
- Expand manifests and metadata structures because Iceberg records statistics, partition information, and references for every data file. section 10.1.1
- Depend on the storage system: HDFS block size matters, while cloud object storage avoids that constraint but still incurs high file-count overhead. section 10.1.1
- Reveal their impact through Iceberg metadata tables, including file counts and size distributions. section 10.1.1
Figure 10.1 More file I/O operations are needed when the same data is spread across a larger number of files, resulting in slower performance. The fewer I/O operations, the more quickly the query can complete.
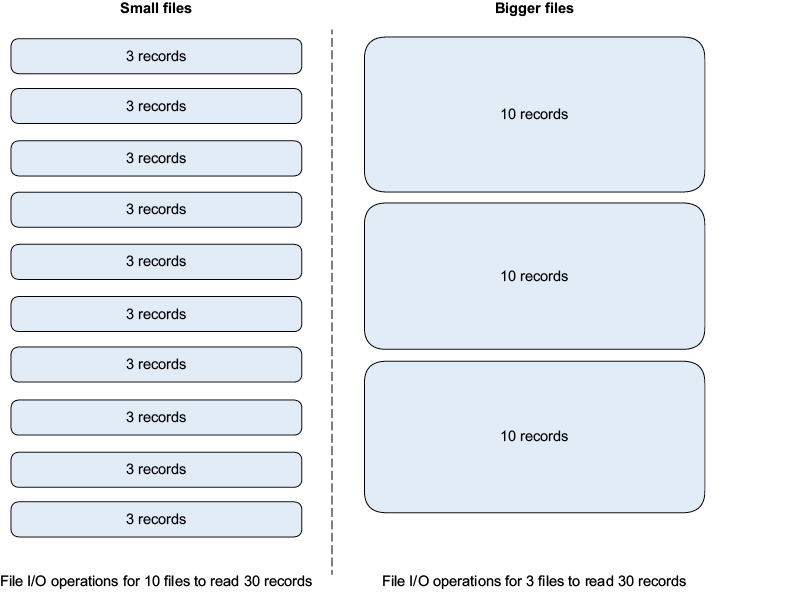
Shows why spreading the same data across more files requires more I/O operations and can slow query completion. section 10.1
