Snapshot-based replication transfers a source dataset's current state to another system instead of emitting every insertion, update, and deletion as a separate change event. section 5.1.2
It fits reference data such as occupations, education levels, marital status, and country codes when values are static or change infrequently. Kafka Connect provides a configuration-driven alternative to custom update services. section 5.1.2
A typical replication flow:
- A source connector reads the current state, such as through a JDBC Source Connector, and writes records to Kafka topics. section 5.1.2
- Independent sink connectors consume those topics and write the data to target systems. section 5.1.2
- Use CDC instead when every source change must be captured from change logs. section 5.1.2
Figure 5.3 Setting up Kafka Connect for data replication involves using PostgreSQL and MongoDB as source systems. Source connectors are responsible for pulling data from these systems and inserting it into Kafka topics. In turn, sink connectors pull the data from Kafka and insert it into the target systems. In this setup, both sink connectors consume data from the same topics, with one inserting the data into an MS SQL database and the other into Amazon S3.
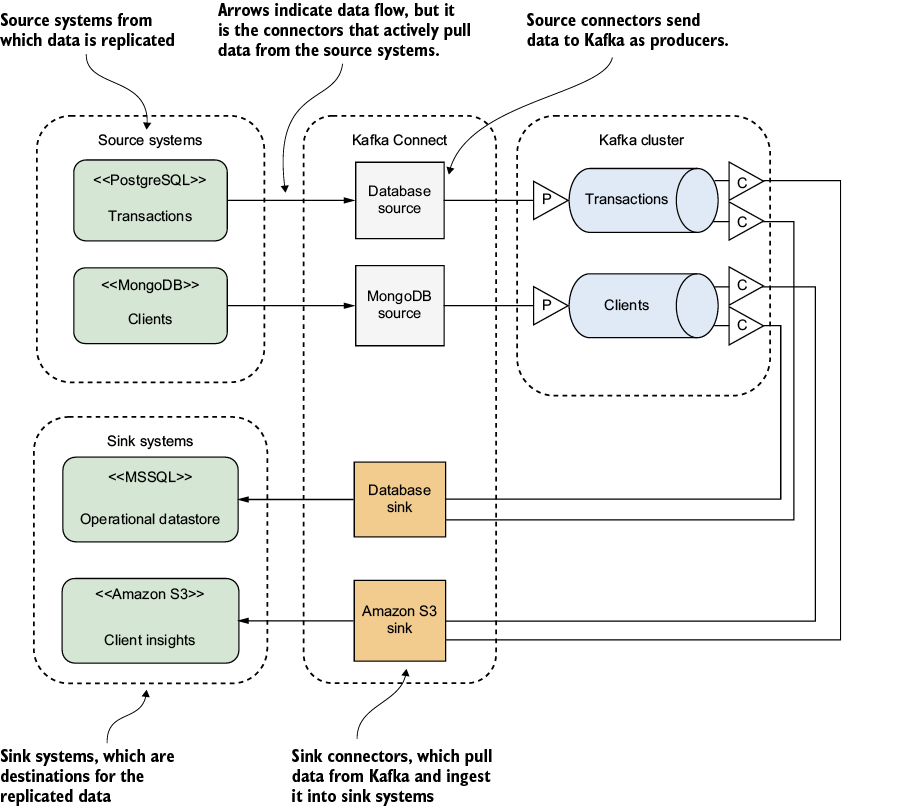
Shows PostgreSQL and MongoDB sources feeding Kafka topics, with independent sinks delivering data to MS SQL and Amazon S3. section 5.1.2
